MLOps Concepts
Imagine you are a data scientist. After weeks of hard work, you have finally trained a machine learning model that performs excellently on the test set. Excitedly, you hand thismodel.pklfile to your software engineer colleague. However, problems follow one after another: How can this model run stably on servers handling millions of requests per day? How can you monitor whether its performance on real data is declining? When new data arrives, how do you automatically retrain and update the model?
This scenario reveals a core challenge in machine learning projects:how to transform experimental model code into a reliable production system that continuously creates value for the business.MLOps is exactly a set of philosophies and practices born to bridge this gap.
Simply put, MLOps isMachine LearningandDevOpsa combination. It draws on the automation, collaboration, and monitoring ideas of DevOps in software development and applies them to the lifecycle management of machine learning systems, aiming to achieveefficient development, reliable deployment, and continuous operation of ML models.。
What is MLOps?
Core Definition
MLOps is a set of engineering practices used tostandardize and automatethe various steps in the lifecycle of machine learning systems, including:
- Model development and experimentation
- Continuous model training and evaluation
- Model deployment and serving
- Monitoring, maintenance, and iteration in production environments
Its ultimate goal isto build reproducible, scalable, auditable, and collaborative machine learning workflowsso that models can move from the lab to production quickly and safely, and continuously maintain their value.
A Simple Analogy: Comparing with DevOps
For a better understanding, we can compare MLOps with the more familiar DevOps:
| Aspect | DevOps (Traditional Software Development) | MLOps (Machine Learning System Development) |
|---|---|---|
| Core Deliverable | Application/Service | Machine learning model + its runtime environment |
| Iteration Object | Code | Code + Data + Model |
| Testing Focus | Functional testing, integration testing | Model performance testing, data validation, concept drift detection |
| Deployment Unit | Executable/Container image | Model file + inference code + specific dependency environment |
| Monitoring Metrics | CPU/memory usage, request latency, error rate | Model prediction quality (e.g., accuracy), input data distribution, business metrics |
This comparison reveals the unique complexity of MLOps: it manages not only code, but alsodataandand modelsThese two dynamically changing elements.
Why MLOps?
Machine learning projects without MLOps often fall into "prototype purgatory" — models remain stuck in the experimental stage forever and fail to make a real impact. MLOps breaks this deadlock by addressing the following key issues:
1. Collaboration and Reproducibility Challenges
- Problem: Data scientists experiment in Jupyter Notebooks, with messy environment dependencies, and experimental steps cannot be reproduced.
- MLOps Solution: Use version control (e.g., Git) to manage code, data versions (e.g., DVC), and model versions; use containerization (e.g., Docker) to freeze environments, ensuring any experiment can be precisely reproduced.
2. Deployment and Operations Complexity
- Problem: Manually deploying models is tedious and error-prone; model serving is difficult to scale, and monitoring is lacking.
- MLOps Solution: Automate CI/CD pipelines to deploy models as API services with one click; leverage cloud-native technologies for elastic scaling; establish comprehensive monitoring dashboards.
3. Model Performance Degradation
- Problem: The data distribution in production changes over time (concept drift), causing model performance to silently degrade without anyone noticing.
- MLOps Solution: Continuously monitor prediction performance and input data distribution, set up automated alerts, and trigger model retraining workflows.
4. Governance and Compliance Requirements
- Problem: It is impossible to trace which model version and which data produced a given prediction, making it difficult to meet audit and regulatory requirements.
- MLOps Solution: End-to-end version tracking, experiment logging, and prediction result traceability.
Core Components and Workflow of MLOps
A typical MLOps system contains multiple collaborating components, and its workflow can be visualized as a loop:
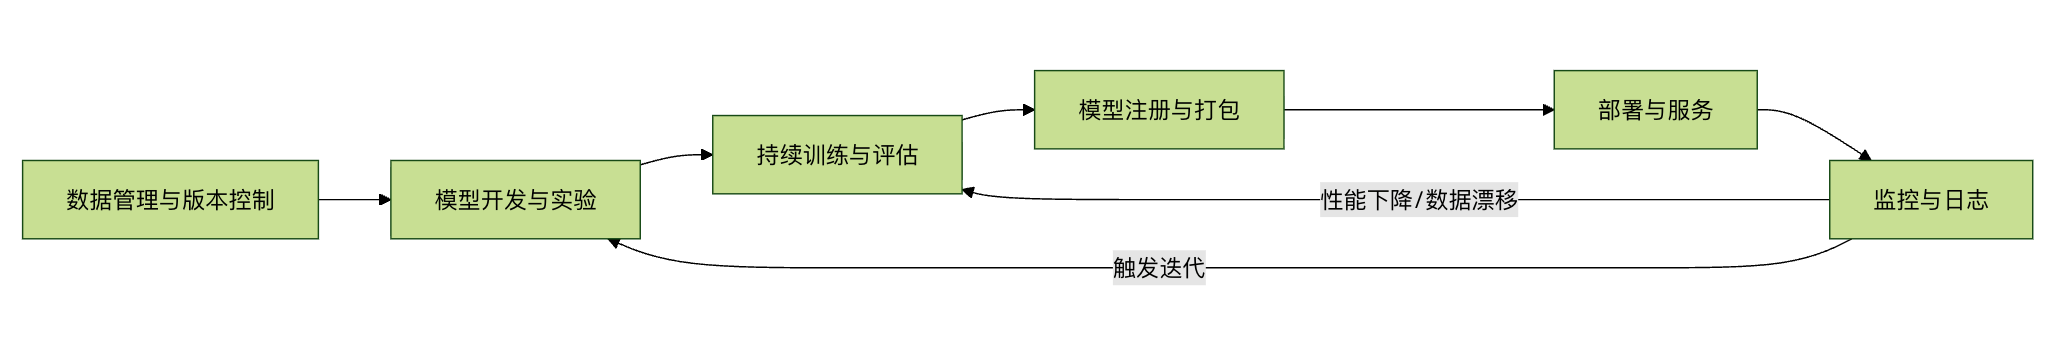
Let's break down each key step in the diagram below:
1. Data Management and Version Control
This is the cornerstone of MLOps. Unlike code, data files are often large and constantly changing.
- Practice: Use tools such asDVC (Data Version Control)orLakeFSto manage data and model files just as Git manages code. They store version metadata of data, while the actual files can be placed in cloud storage.
- Example: Each experiment can be associated with a specific data snapshot, ensuring reproducible results.
2. Model Development and Experimentation
This is the main battlefield for data scientists, but it requires engineering discipline.
- Practice: Refactor experimental code from notebooks into modular Python scripts; useMLflow TrackingorWeights & Biasesto record hyperparameters, metrics, and output models for each experiment for easy comparison.
3. Continuous Training and Evaluation
When new data arrives or performance degradation is detected, the system should be able to retrain the model automatically or semi-automatically.
- Practice: Build automated training pipelines (e.g., usingKubeflow PipelinesorApache Airflow). The pipeline includes data validation, feature engineering, model training, and evaluation (ona validation set distinct from the training set) and other steps. Only models that pass evaluation can proceed to the next stage.
4. Model Registration and Packaging
Trained models need to be properly managed and prepared for deployment.
- Practice: Use amodel registry(e.g., MLflow Model Registry). It stores, annotates, and manages models as versionable assets. Models are typically packaged together with inference code intoDocker container imagesto ensure consistency with the production environment.
5. Deployment and Serving
Provide the model to users or other systems.
- Modes:
- Batch prediction: Periodically make predictions on large amounts of data and generate reports.
- Real-time API serving: The model acts as a REST API or gRPC service, responding to requests in real time. Common tools includeFastAPI, TensorFlow Serving, TorchServeor managed services from cloud providers.
- Strategies: You can adoptblue-green deploymentoror canary releasesto gradually shift traffic to the new model and reduce risk.
6. Monitoring and Logging
This is the "eyes" that ensure the production model runs healthily.
- Monitoring Content:
- System metrics: API latency, throughput, error rate, resource utilization.
- Model metrics: Distribution of prediction results, changes in important features (detecting data drift).
- Business metrics: The ultimate business impact of model decisions (e.g., click-through rate, conversion rate).
- Practice: Integrate monitoring tools (e.g.,Prometheus, Grafana) and logging systems (e.g.,ELK Stack), and set up alert rules for key metrics.
A Simplified MLOps Practice Example
Let's walk through a conceptual code flow to see how to implement experiment tracking, model registration, and packaging using MLflow, a popular tool.
Example
import mlflow
import mlflow.sklearn
from sklearn.datasets import load_iris
from sklearn.ensemble import RandomForestClassifier
from sklearn.model_selection import train_test_split
from sklearn.metrics import accuracy_score
# 2. Set up the MLflow tracking server (assuming it is already running locally)
mlflow.set_tracking_uri("http://127.0.0.1:5000")
mlflow.set_experiment("Iris_Classification")
# 3. Start an experiment run
with mlflow.start_run():
# Load data and split it
data = load_iris()
X_train, X_test, y_train, y_test = train_test_split(data.data, data.target, test_size=0.2)
# Define and train the model
n_estimators = 100
model = RandomForestClassifier(n_estimators=n_estimators, random_state=42)
model.fit(X_train, y_train)
# Predict and evaluate
y_pred = model.predict(X_test)
acc = accuracy_score(y_test, y_pred)
# 4. Log experiment information to the MLflow Tracking Server
mlflow.log_param("n_estimators", n_estimators) # Log hyperparameters
mlflow.log_metric("accuracy", acc) # Log evaluation metrics
# 5. Log the model itself (including its dependency environment)
# mlflow.sklearn.log_model logs the model and generates a conda.yaml environment file
mlflow.sklearn.log_model(model, "random_forest_model")
print(f"Model training completed, accuracy: {acc:.4f}")
print(f"Experiment logged. You can view it in the MLflow UI (http://127.0.0.1:5000).")
# 6. (Next step) In the MLflow UI, you can "register" this logged model in the Model Registry.
# 7. Then, you can retrieve the model from the Registry and package it as a Docker image using the `mlflow models build-docker` command.
# 8. Finally, deploy this image to Kubernetes or a cloud server to serve the model.
Code explanation:
- This example demonstrates the core aspects of MLOps:Experiment trackingandModel loggingThese are essential.
mlflow.log_paramandmlflow.log_metricIt ensures traceability of experiments.mlflow.sklearn.log_modelIt not only saves the model file but also automatically records the Python library versions (environment) used to create the model, which is a key step toward reproducibility.- Subsequent registration, packaging, and deployment steps are usually completed in the UI or through CI/CD pipelines.
MLOps Maturity Levels
Implementing MLOps is not a one-time effort; it is generally considered to have three evolutionary stages:
- Basic MLOps (manual process): Deployment and training processes are triggered manually, with limited monitoring. This is the starting point for many teams.
- Intermediate MLOps (automated pipelines): Implements continuous integration (CI)Continuous Integration (CI)andContinuous Delivery (CD)for model training and deployment, with a high degree of automation.
- Advanced MLOps (Continuous Training, CT): The system has complete automated monitoring and feedback loops, capable of automatically triggering data collection, retraining, evaluation, and deployment, achieving trueContinuous Training。
Summary and Outlook
MLOps is not a specific tool, but acomprehensive framework covering culture, processes, and technology. It requires close collaboration among data scientists, machine learning engineers, and operations engineers.
For beginners, understanding the concepts of MLOps is the first step toward building reliable machine learning systems. You can start with the following practices:
- Use Git for strict code version control。
- Try MLflow to manage your experiments and models。
- Serve your model, for example, write a simple prediction API with FastAPI.
- Think about how to monitor your model prediction results。
As machine learning becomes increasingly applied in industry, MLOps has become a key engineering capability for ensuring the success, controllability, and scalability of ML projects. Mastering the MLOps mindset can help you turn the models in your hands from brilliant crystals in the laboratory into a stable engine that drives business growth.
Other extensions