Machine Learning Project Lifecycle
A machine learning project is like building a house; it requires a complete process from design blueprints to construction and final inspection. Every step is crucial and indispensable.
The six core phases of the machine learning workflow:
- Problem Definition: clarify what problem to solve
- Data Collection: acquire relevant data
- Data Preparation: clean and preprocess data
- Model Training: select algorithms and train models
- Model Evaluation: evaluate model performance
- Model Deployment: put the model into use
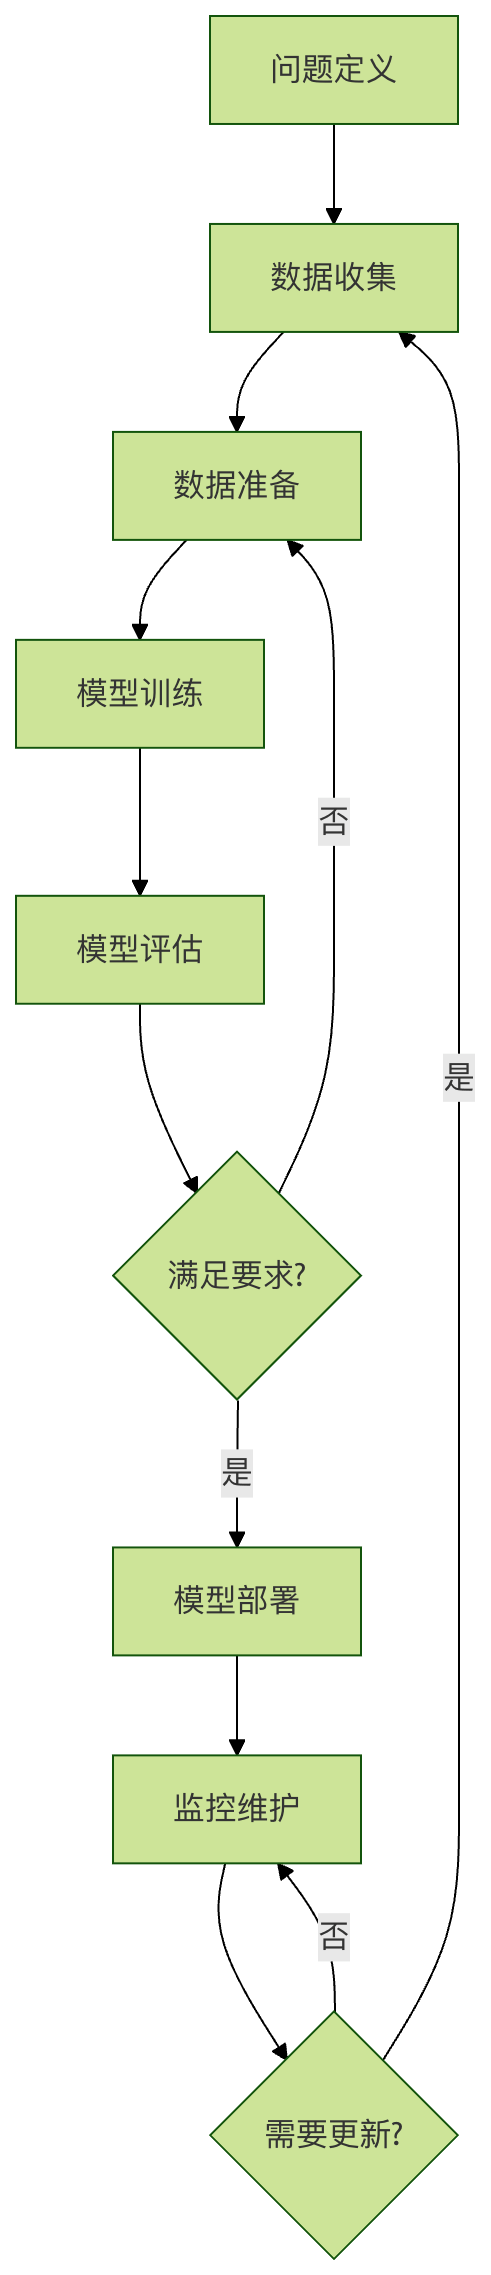
Phase 1: Problem Definition
Define the business problem
Problem definition is the most important starting point of a machine learning project, just as you need to know your destination before using navigation.
Key Questions
What problem are we trying to solve?
- Classification: determine whether an email is spam
- Regression: predict house prices
- Clustering: customer segmentation
- Anomaly detection: detect credit card fraud
Why is this problem important?
- Business value: improve efficiency, reduce costs, increase revenue
- User value: improve experience, provide personalized services
What are the criteria for success?
- Quantitative metrics: accuracy above 90%
- Business metrics: conversion rate increase of 20%
Problem Definition Example
Example
class ProblemDefinition:
def __init__(self):
# Business problem
self.business_problem = "User purchase conversion rate is low; recommendation accuracy needs to be improved"
# Technical problem
self.technical_problem = "Predict products a user is likely to purchase based on user behavior"
# Problem type
self.problem_type = "Recommendation system (classification + ranking)"
# Success criteria
self.success_criteria = {
"Click-through rate improvement": "15%",
"Conversion rate improvement": "10%",
"Recommendation accuracy": "80%"
}
# Constraints
self.constraints = {
"Response time": "< 100ms",
"Data privacy": "Comply with GDPR requirements",
"Computing resources": "Existing server configuration"
}
def define_features_and_labels(self):
"""Define features and labels"""
features = {
"User features": ["Age", "Gender", "Purchase history", "Browsing behavior"],
"Product features": ["Category", "Price", "Rating", "Stock"],
"Contextual features": ["Time", "Device", "Geographic location"]
}
labels = {
"Primary label": "Whether clicked",
"Secondary label": "Whether purchased",
"Auxiliary label": "Dwell time"
}
return features, labels
def print_definition(self):
"""Print problem definition"""
print("=" * 50)
print("Machine Learning Problem Definition")
print("=" * 50)
print(f"Business problem: {self.business_problem}")
print(f"Technical problem: {self.technical_problem}")
print(f"Problem type: {self.problem_type}")
print("\nSuccess criteria: ")
for metric, target in self.success_criteria.items():
print(f" {metric}:{target}")
print("\nConstraints: ")
for constraint, limit in self.constraints.items():
print(f" {constraint}:{limit}")
features, labels = self.define_features_and_labels()
print("\nFeature definitions: ")
for category, items in features.items():
print(f" {category}:{', '.join(items)}")
print("\nLabel definitions: ")
for label_type, label_name in labels.items():
print(f" {label_type}:{label_name}")
# Usage example
problem = ProblemDefinition()
problem.print_definition()
Output:
==================================================
机器学习问题定义
==================================================
业务问题:用户购买转化率低,需要提高推荐精准度
技术问题:基于用户行为预测用户可能购买的商品
问题类型:推荐系统(分类+排序)

成功标准:
  点击率提升:15%
  转化率提升:10%
  推荐准确率:80%

约束条件:
  响应时间:< 100ms
  数据隐私:符合 GDPR 要求
  计算资源:现有服务器配置

特征定义:
  用户特征:年龄, 性别, 购买历史, 浏览行为
  商品特征:类别, 价格, 评分, 库存
  上下文特征:时间, 设备, 地理位置

标签定义:
  主要标签:是否点击
  次要标签:是否购买
  辅助标签:停留时间
Phase 2: Data Collection
Data Sources
Data is the fuel of machine learning; without suitable data, no matter how good the algorithm is, it cannot work effectively.
Common Data Sources
- Internal data: company business data, user behavior data
- External data: public datasets, third-party data services
- Web scraping: web data, social media data
- Sensor data: IoT devices, monitoring systems
Data Collection Example
Example
import pandas as pd
import numpy as np
from datetime import datetime, timedelta
class DataCollector:
def __init__(self):
self.collected_data = {}
def collect_user_data(self, n_users=1000):
"""Collect user data"""
np.random.seed(42)
user_data = {
'user_id': range(1, n_users + 1),
'age': np.random.randint(18, 65, n_users),
'gender': np.random.choice(['Male', 'Female'], n_users),
'city': np.random.choice(['Beijing', 'Shanghai', 'Guangzhou', 'Shenzhen'], n_users),
'registration_date': [
datetime.now() - timedelta(days=np.random.randint(1, 365))
for _ in range(n_users)
]
}
self.collected_data['users'] = pd.DataFrame(user_data)
print(f"Collected {len(user_data['user_id'])} user data records")
return self.collected_data['users']
def collect_behavior_data(self, n_behaviors=5000):
"""Collect user behavior data"""
np.random.seed(42)
user_ids = np.random.choice(range(1, 1001), n_behaviors)
product_ids = np.random.choice(range(1, 501), n_behaviors)
behavior_data = {
'behavior_id': range(1, n_behaviors + 1),
'user_id': user_ids,
'product_id': product_ids,
'behavior_type': np.random.choice(
['View', 'Click', 'Add to cart', 'Purchase'], n_behaviors,
p=[0.4, 0.3, 0.2, 0.1]
),
'timestamp': [
datetime.now() - timedelta(minutes=np.random.randint(1, 10080))
for _ in range(n_behaviors)
],
'duration': np.random.exponential(30, n_behaviors) # Dwell time (seconds)
}
self.collected_data['behaviors'] = pd.DataFrame(behavior_data)
print(f"Collected {len(behavior_data['behavior_id'])} behavior data records")
return self.collected_data['behaviors']
def collect_product_data(self, n_products=500):
"""Collect product data"""
np.random.seed(42)
categories = ['Electronics', 'Clothing', 'Food', 'Home', 'Books']
product_data = {
'product_id': range(1, n_products + 1),
'category': np.random.choice(categories, n_products),
'price': np.random.uniform(10, 1000, n_products),
'rating': np.random.uniform(3.0, 5.0, n_products),
'stock': np.random.randint(0, 1000, n_products)
}
self.collected_data['products'] = pd.DataFrame(product_data)
print(f"Collected {len(product_data['product_id'])} product data records")
return self.collected_data['products']
def get_data_summary(self):
"""Get data summary"""
print("\nData collection summary: ")
for name, df in self.collected_data.items():
print(f"\n{name} dataset: ")
print(f" Shape: {df.shape}")
print(f" Columns: {list(df.columns)}")
print(f" Missing values: {df.isnull().sum().sum()}")
print(f" Sample data:")
print(df.head(2))
# Usage example
collector = DataCollector()
collector.collect_user_data()
collector.collect_behavior_data()
collector.collect_product_data()
collector.get_data_summary()
Phase 3: Data Preparation
Importance of Data Preparation
Data preparation accounts for 60-80% of the time in a machine learning project, just as important as the preparation work before cooking.
Main Tasks of Data Preparation
- Data cleaning: handle missing values, outliers, duplicate values
- Feature engineering: create new features, select important features
- Data transformation: standardization, normalization, encoding
- Data splitting: training set, validation set, test set
Data Preparation Example
Example
import pandas as pd
import numpy as np
from sklearn.preprocessing import StandardScaler, LabelEncoder
from sklearn.model_selection import train_test_split
class DataPreparer:
def __init__(self, data):
self.data = data.copy()
self.processed_data = None
def clean_data(self):
"""Data cleaning"""
print("Starting data cleaning...")
# 1. Handle missing values
print(f"Missing values before processing: {self.data.isnull().sum().sum()}")
# Fill numeric columns with mean
numeric_columns = self.data.select_dtypes(include=[np.number]).columns
for col in numeric_columns:
if self.data[col].isnull().sum() > 0:
self.data[col].fillna(self.data[col].mean(), inplace=True)
# Fill categorical columns with mode
categorical_columns = self.data.select_dtypes(include=['object']).columns
for col in categorical_columns:
if self.data[col].isnull().sum() > 0:
mode_val = self.data[col].mode()[0]
self.data[col].fillna(mode_val, inplace=True)
print(f"Missing values after processing: {self.data.isnull().sum().sum()}")
# 2. Handle duplicate values
duplicates_before = self.data.duplicated().sum()
self.data.drop_duplicates(inplace=True)
duplicates_after = self.data.duplicated().sum()
print(f"Duplicates removed: {duplicates_before - duplicates_after} rows")
# 3. Handle outliers (simple method: use IQR)
for col in numeric_columns:
Q1 = self.data[col].quantile(0.25)
Q3 = self.data[col].quantile(0.75)
IQR = Q3 - Q1
lower_bound = Q1 - 1.5 * IQR
upper_bound = Q3 + 1.5 * IQR
outliers = ((self.data[col] < lower_bound) |
(self.data[col] > upper_bound)).sum()
if outliers > 0:
# Replace outliers with boundary values
self.data[col] = self.data[col].clip(lower_bound, upper_bound)
print(f"Processed {outliers} outliers in column {col}")
return self.data
def feature_engineering(self):
"""Feature engineering"""
print("\nStarting feature engineering...")
# 1. Create new features (example)
if 'price' in self.data.columns and 'rating' in self.data.columns:
# Create a price-performance ratio feature
self.data['price_per_rating'] = self.data['price'] / self.data['rating']
print("Created new feature: price_per_rating")
# 2. Feature Selection (Simple Example: Remove Low-Variance Features)
numeric_columns = self.data.select_dtypes(include=[np.number]).columns
low_variance_features = []
for col in numeric_columns:
if self.data[col].var() < 0.01: # Variance Threshold
low_variance_features.append(col)
if low_variance_features:
self.data.drop(columns=low_variance_features, inplace=True)
print(f"Removing low-variance features: {low_variance_features}")
return self.data
def transform_data(self):
"""Data Transformation"""
print("\n"Starting data transformation...")
# 1. Encode categorical variables
categorical_columns = self.data.select_dtypes(include=['object']).columns
label_encoders = {}
for col in categorical_columns:
le = LabelEncoder()
self.data[col] = le.fit_transform(self.data[col])
label_encoders[col] = le
print(f"Encoding categorical variable: {col}")
# 2. Standardize numerical variables
numeric_columns = self.data.select_dtypes(include=[np.number]).columns
scaler = StandardScaler()
if len(numeric_columns) > 0:
self.data[numeric_columns] = scaler.fit_transform(self.data[numeric_columns])
print(f"Standardizing numerical variables: {list(numeric_columns)}")
return self.data, label_encoders, scaler
def split_data(self, target_column, test_size=0.2, val_size=0.2):
"""Data Splitting"""
print(f"\n"Starting data splitting (test set ratio: {test_size}, validation set ratio: {val_size})...")
X = self.data.drop(columns=[target_column])
y = self.data[target_column]
# First separate out the test set
X_temp, X_test, y_temp, y_test = train_test_split(
X, y, test_size=test_size, random_state=42
)
# Then separate out the validation set from the remaining data
val_size_adjusted = val_size / (1 - test_size)
X_train, X_val, y_train, y_val = train_test_split(
X_temp, y_temp, test_size=val_size_adjusted, random_state=42
)
print(f"Training set size: {X_train.shape)
print(f"Validation set size: {X_val.shape)
print(f"Test set size: {X_test.shape)
return {
'X_train': X_train, 'y_train': y_train,
'X_val': X_val, 'y_val': y_val,
'X_test': X_test, 'y_test': y_test
}
def prepare_pipeline(self, target_column):
"""Complete Data Preparation Pipeline"""
print("=" * 50)
print("Data Preparation Pipeline")
print("=" * 50)
# 1. Data cleaning
self.clean_data()
# 2. Feature engineering
self.feature_engineering()
# 3. Data transformation
processed_data, encoders, scaler = self.transform_data()
# 4. Data splitting
splits = self.split_data(target_column)
self.processed_data = processed_data
return splits, encoders, scaler
# Create sample data and demonstrate data preparation
np.random.seed(42)
sample_data = pd.DataFrame({
'age': np.random.randint(18, 65, 1000),
'income': np.random.normal(50000, 15000, 1000),
'gender': np.random.choice(['Male', 'Female'], 1000),
'city': np.random.choice(['Beijing', 'Shanghai', 'Guangzhou'], 1000),
'target': np.random.choice([0, 1], 1000)
})
# Add some missing values and outliers
sample_data.loc[np.random.choice(1000, 50), 'income'] = np.nan
sample_data.loc[np.random.choice(1000, 20), 'age'] = np.random.randint(100, 150)
preparer = DataPreparer(sample_data)
splits, encoders, scaler = preparer.prepare_pipeline('target')
Phase 4: Model Training
Model Selection Strategy
Choosing the right model is the key to success, just like choosing the right tool for the job.
Model Selection Considerations
- Problem type: classification, regression, clustering, etc.
- Data characteristics: data size, number of features, data type
- Performance requirements: accuracy, speed, interpretability
- Resource constraints: computational resources, time limits
Model Training Example
Example
from sklearn.linear_model import LogisticRegression, LinearRegression
from sklearn.ensemble import RandomForestClassifier, RandomForestRegressor
from sklearn.svm import SVC, SVR
from sklearn.metrics import accuracy_score, mean_squared_error, classification_report
class ModelTrainer:
def __init__(self):
self.models = {}
self.trained_models = {}
def register_model(self, name, model, problem_type):
"""Register Model"""
self.models[name] = {
'model': model,
'problem_type': problem_type
}
print(f"Registering model: {name} ({problem_type})")
def train_single_model(self, name, X_train, y_train):
"""Train a Single Model"""
if name not in self.models:
raise ValueError(f"Model {name} is not registered")
model_info = self.models[name]
model = model_info['model']
print(f"\n"Training model: {name}")
model.fit(X_train, y_train)
self.trained_models[name] = model
print(f"Model {name} training complete")
return model
def train_all_models(self, X_train, y_train):
"""Train All Registered Models"""
print("\n"Starting to train all models...")
for name in self.models.keys():
try:
self.train_single_model(name, X_train, y_train)
except Exception as e:
print(f"Error training model {name}: {e}")
return self.trained_models
def evaluate_models(self, X_test, y_test):
"""Evaluate All Trained Models"""
print("\n"Model evaluation results:")
print("-" * 50)
results = {}
for name, model in self.trained_models.items():
problem_type = self.models[name]['problem_type']
# Predictions
y_pred = model.predict(X_test)
# Select evaluation metrics based on problem type
if problem_type == 'classification':
accuracy = accuracy_score(y_test, y_pred)
results[name] = {'accuracy': accuracy}
print(f"{name}: Accuracy = {accuracy:.4f}")
# Detailed report
print(classification_report(y_test, y_pred))
elif problem_type == 'regression':
mse = mean_squared_error(y_test, y_pred)
rmse = np.sqrt(mse)
results[name] = {'mse': mse, 'rmse': rmse}
print(f"{name}: MSE = {mse:.4f}, RMSE = {rmse:.4f}")
print("-" * 50)
return results
def get_best_model(self, results, metric='accuracy'):
"""Get Best Model"""
if not results:
return None
best_model_name = max(results.keys(), key=lambda x: results[x].get(metric, 0))
best_score = results[best_model_name][metric]
print(f"\n"Best model: {best_model_name} ({metric} = {best_score:.4f})")
return best_model_name, self.trained_models[best_model_name]
# Usage example
trainer = ModelTrainer()
# Register different types of models
trainer.register_model('Logistic Regression', LogisticRegression(random_state=42), 'classification')
trainer.register_model('Random Forest', RandomForestClassifier(n_estimators=100, random_state=42), 'classification')
trainer.register_model('Support Vector Machine', SVC(random_state=42), 'classification')
# Create training data
X_train = splits['X_train']
y_train = splits['y_train']
X_test = splits['X_test']
y_test = splits['y_test']
# Train all models
trained_models = trainer.train_all_models(X_train, y_train)
# Evaluate models
results = trainer.evaluate_models(X_test, y_test)
# Get the best model
best_name, best_model = trainer.get_best_model(results)
Phase 5: Model Evaluation
Evaluation Metric Selection
Choosing the right evaluation metric is like choosing the right ruler, different metrics are suitable for different scenarios.
Common Evaluation Metrics
Classification Problems:
- Accuracy: the proportion of correct predictions
- Precision: the proportion of predicted positive samples that are actually positive
- Recall: the proportion of actual positive samples that are correctly predicted as positive
- F1 Score: the harmonic mean of precision and recall
Regression Problems:
- Mean Squared Error (MSE): the average of the squared differences between predicted and true values
- Root Mean Squared Error (RMSE): the square root of MSE
- Mean Absolute Error (MAE): the average of the absolute differences between predicted and true values
- R² Score: the proportion of variance explained by the model
Model Evaluation Example
Example
import matplotlib.pyplot as plt
from sklearn.metrics import (
accuracy_score, precision_score, recall_score, f1_score,
confusion_matrix, roc_curve, auc
)
class ModelEvaluator:
def __init__(self):
self.evaluation_results = {}
def evaluate_classification(self, y_true, y_pred, y_prob=None, model_name="Model"):
"""Evaluate Classification Model"""
results = {}
# Basic metrics
results['accuracy'] = accuracy_score(y_true, y_pred)
results['precision'] = precision_score(y_true, y_pred, average='weighted')
results['recall'] = recall_score(y_true, y_pred, average='weighted')
results['f1'] = f1_score(y_true, y_pred, average='weighted')
print(f"\n"{model_name} Classification Evaluation Results:")
print(f"Accuracy: {results['accuracy']:.4f}")
print(f"Precision: {results['precision']:.4f}")
print(f"Recall: {results['recall']:.4f}")
print(f"F1 Score: {results['f1']:.4f}")
# Confusion matrix
cm = confusion_matrix(y_true, y_pred)
print(f"\n"Confusion matrix:")
print(cm)
# ROC curve (if probability predictions are available)
if y_prob is not None and len(np.unique(y_true)) == 2:
fpr, tpr, thresholds = roc_curve(y_true, y_prob[:, 1])
roc_auc = auc(fpr, tpr)
results['roc_auc'] = roc_auc
# Plot ROC curve
plt.figure(figsize=(8, 6))
plt.plot(fpr, tpr, color='darkorange', lw=2,
label=f'ROC Curve (AUC = {roc_auc:.2f})')
plt.plot([0, 1], [0, 1], color='navy', lw=2, linestyle='--')
plt.xlim([0.0, 1.0])
plt.ylim([0.0, 1.05])
plt.xlabel('False Positive Rate')
plt.ylabel('True Positive Rate')
plt.title(f'{model_name} ROC Curve')
plt.legend(loc="lower right")
plt.grid(True)
plt.show()
self.evaluation_results[model_name] = results
return results
def evaluate_regression(self, y_true, y_pred, model_name="Model"):
"""Evaluate Regression Model"""
results = {}
# Basic metrics
mse = np.mean((y_true - y_pred) ** 2)
rmse = np.sqrt(mse)
mae = np.mean(np.abs(y_true - y_pred))
# R² Score
ss_res = np.sum((y_true - y_pred) ** 2)
ss_tot = np.sum((y_true - np.mean(y_true)) ** 2)
r2 = 1 - (ss_res / ss_tot)
results['mse'] = mse
results['rmse'] = rmse
results['mae'] = mae
results['r2'] = r2
print(f"\n"{model_name} Regression Evaluation Results:")
print(f"Mean Squared Error (MSE): {mse:.4f}")
print(f"Root Mean Squared Error (RMSE): {rmse:.4f}")
print(f"Mean Absolute Error (MAE): {mae:.4f}")
print(f"R² Score: {r2:.4f}")
# Plot predicted vs. actual values
plt.figure(figsize=(8, 6))
plt.scatter(y_true, y_pred, alpha=0.6)
plt.plot([y_true.min(), y_true.max()], [y_true.min(), y_true.max()],
'r--', lw=2)
plt.xlabel('Actual Values')
plt.ylabel('Predicted Values')
plt.title(f'{model_name} Predicted vs. Actual Values')
plt.grid(True)
plt.show()
self.evaluation_results[model_name] = results
return results
def compare_models(self):
"""Compare All Evaluated Models"""
if not self.evaluation_results:
print("No comparable model evaluation results")
return
print("\n"Model Comparison:")
print("-" * 50)
# Create comparison table
comparison_data = []
for model_name, results in self.evaluation_results.items():
row = [model_name]
for metric, value in results.items():
row.append(f"{value:.4f}")
comparison_data.append(row)
# Print table
headers = ["Model Name"] + list(self.evaluation_results.values())[0].keys()
print("\t".join(headers))
for row in comparison_data:
print("\t".join(row))
# Usage example
evaluator = ModelEvaluator()
# Evaluate classification model
y_pred_class = best_model.predict(X_test)
y_prob_class = best_model.predict_proba(X_test)
evaluator.evaluate_classification(y_test, y_pred_class, y_prob_class, "Best Classification Model")
# Compare all models
evaluator.compare_models()
Phase 6: Model Deployment
Deployment Strategy
Model deployment is the process of putting a model into practical use, just like bringing a developed product to market.
Deployment Methods
- Batch prediction: periodically process large amounts of data
- Real-time prediction: online service, instant response
- Embedded deployment: integrate the model into existing systems
- Edge deployment: run the model on devices
Model Deployment Example
Example
import pickle
import json
from datetime import datetime
class ModelDeployer:
def __init__(self):
self.deployed_models = {}
self.deployment_logs = []
def save_model(self, model, model_name, filepath=None):
"""Save Model"""
if filepath is None:
filepath = f"{model_name}.pkl"
with open(filepath, 'wb') as f:
pickle.dump(model, f)
print(f"Model {model_name} saved to {filepath}")
# Record deployment log
log_entry = {
'timestamp': datetime.now().isoformat(),
'action': 'save_model',
'model_name': model_name,
'filepath': filepath
}
self.deployment_logs.append(log_entry)
return filepath
def load_model(self, model_name, filepath):
"""Load Model"""
with open(filepath, 'rb') as f:
model = pickle.load(f)
self.deployed_models[model_name] = model
print(f"Model {model_name} loaded from {filepath}")
# Record deployment log
log_entry = {
'timestamp': datetime.now().isoformat(),
'action': 'load_model',
'model_name': model_name,
'filepath': filepath
}
self.deployment_logs.append(log_entry)
return model
def create_prediction_service(self, model_name, encoders=None, scaler=None):
"""Create Prediction Service"""
if model_name not in self.deployed_models:
raise ValueError(f"Model {model_name} is not deployed")
model = self.deployed_models[model_name]
def predict_service(input_data):
"""Prediction Service Function"""
try:
# Data preprocessing
if encoders:
for col, encoder in encoders.items():
if col in input_data.columns:
input_data[col] = encoder.transform(input_data[col])
if scaler:
numeric_cols = input_data.select_dtypes(include=['number']).columns
input_data[numeric_cols] = scaler.transform(input_data[numeric_cols])
# Prediction
prediction = model.predict(input_data)
# If it is a classification model, also return probabilities
if hasattr(model, 'predict_proba'):
probability = model.predict_proba(input_data)
return {
'prediction': prediction.tolist(),
'probability': probability.tolist(),
'status': 'success',
'timestamp': datetime.now().isoformat()
}
else:
return {
'prediction': prediction.tolist(),
'status': 'success',
'timestamp': datetime.now().isoformat()
}
except Exception as e:
return {
'error': str(e),
'status': 'error',
'timestamp': datetime.now().isoformat()
}
# Record service creation log
log_entry = {
'timestamp': datetime.now().isoformat(),
'action': 'create_service',
'model_name': model_name
}
self.deployment_logs.append(log_entry)
return predict_service
def monitor_model(self, model_name, input_data, true_labels=None):
"""Monitor Model Performance"""
if model_name not in self.deployed_models:
raise ValueError(f"Model {model_name} is not deployed")
predict_service = self.create_prediction_service(model_name)
# Get prediction results
result = predict_service(input_data)
# Monitoring information
monitoring_info = {
'timestamp': datetime.now().isoformat(),
'model_name': model_name,
'input_shape': input_data.shape,
'prediction_count': len(result.get('prediction', [])),
'status': result.get('status', 'unknown')
}
# If true labels are available, compute performance metrics
if true_labels is not None and 'prediction' in result:
predictions = result['prediction']
if len(predictions) == len(true_labels):
accuracy = accuracy_score(true_labels, predictions)
monitoring_info['accuracy'] = accuracy
print("Model monitoring information:")
for key, value in monitoring_info.items():
print(f" {key}: {value}")
return monitoring_info
def get_deployment_logs(self):
"""Get Deployment Logs"""
return self.deployment_logs
# Usage example
deployer = ModelDeployer()
# Save the best model
model_path = deployer.save_model(best_model, "best_classification_model")
# Load the model
deployer.load_model("best_classification_model", model_path)
# Create prediction service
prediction_service = deployer.create_prediction_service(
"best_classification_model", encoders, scaler
)
# Use prediction service
test_input = X_test.head(5)
prediction_result = prediction_service(test_input)
print("\n"Prediction results:")
print(json.dumps(prediction_result, indent=2, ensure_ascii=False))
# Monitor model
deployer.monitor_model("best_classification_model", test_input, y_test.head(5).values)
Complete Workflow Example
Example
class MLProjectPipeline:
def __init__(self):
self.data_collector = DataCollector()
self.data_preparer = None
self.model_trainer = ModelTrainer()
self.model_evaluator = ModelEvaluator()
self.model_deployer = ModelDeployer()
def run_complete_pipeline(self, target_column):
"""Run the complete machine learning pipeline"""
print("=" * 60)
print("Complete machine learning project workflow")
print("=" * 60)
# 1. Data Collection
print("\nStep 1: Data Collection")
print("-" * 30)
user_data = self.data_collector.collect_user_data(1000)
behavior_data = self.data_collector.collect_behavior_data(5000)
# Merge data (simplified example)
merged_data = pd.merge(user_data, behavior_data, on='user_id', how='inner')
# Create target variable (example: whether to purchase)
merged_data['purchased'] = (merged_data['behavior_type'] == 'Purchase').astype(int)
# 2. Data Preparation
print("\nStep 2: Data Preparation")
print("-" * 30)
# Select feature columns
feature_columns = ['age', 'gender', 'city', 'duration']
if all(col in merged_data.columns for col in feature_columns):
data_for_ml = merged_data[feature_columns + ['purchased']].copy()
# Handle categorical variables
data_for_ml['gender'] = data_for_ml['gender'].map({'Male': 0, 'Female': 1})
data_for_ml['city'] = data_for_ml['city'].map({'Beijing': 0, 'Shanghai': 1, 'Guangzhou': 2})
# Data Preparation
self.data_preparer = DataPreparer(data_for_ml)
splits, encoders, scaler = self.data_preparer.prepare_pipeline('purchased')
# 3. Model Training
print("\nStep 3: Model Training")
print("-" * 30)
# Register model
self.model_trainer.register_model(
'Logistic Regression', LogisticRegression(random_state=42), 'classification'
)
self.model_trainer.register_model(
'Random Forest', RandomForestClassifier(n_estimators=100, random_state=42), 'classification'
)
# Train model
trained_models = self.model_trainer.train_all_models(
splits['X_train'], splits['y_train']
)
# 4. Model Evaluation
print("\nStep 4: Model Evaluation")
print("-" * 30)
results = self.model_trainer.evaluate_models(
splits['X_test'], splits['y_test']
)
best_name, best_model = self.model_trainer.get_best_model(results)
# 5. Model Deployment
print("\nStep 5: Model Deployment")
print("-" * 30)
# Save model
model_path = self.model_deployer.save_model(best_model, "production_model")
# Create prediction service
prediction_service = self.model_deployer.create_prediction_service(
"production_model"
)
# Test prediction service
test_input = splits['X_test'].head(3)
prediction_result = prediction_service(test_input)
print("\nPrediction service test result:")
print(json.dumps(prediction_result, indent=2, ensure_ascii=False))
print("\n" + "=" * 60)
print("Machine learning project workflow complete!")
print("=" * 60)
return {
'data': data_for_ml,
'splits': splits,
'best_model': best_model,
'best_model_name': best_name,
'evaluation_results': results,
'prediction_service': prediction_service
}
else:
print("Data columns are incomplete, cannot continue the workflow")
return None
# Run complete workflow
pipeline = MLProjectPipeline()
project_results = pipeline.run_complete_pipeline('purchased')