Machine Learning - Learning Path
Machine learning is one of the hottest technical fields today; it enables computers to learn from data and make predictions or decisions.
For beginners, facing a vast array of algorithms, mathematical theories, and programming tools, it is easy to feel confused and not know where to start.
This article will introduce a machine learning roadmap from zero foundation to practical capability.
| Machine Learning - Course List | |
|---|---|
| Basic Introduction | |
| Basic Introduction | Machine Learning Tutorial |
| Basic Introduction | Introduction to Machine Learning |
| Basic Introduction | Machine Learning Lifecycle |
| Basic Introduction | How Machine Learning Works |
| Basic Introduction | Basic Machine Learning Terminology |
| Basic Introduction | Introduction to Machine Learning with Python |
| Basic Introduction | Python Machine Learning Libraries |
| Basic Introduction | Common Data Types |
| Basic Introduction | Machine Learning Applications |
| Data Processing and Statistics | |
| Data Processing and Statistics | Data Understanding |
| Data Processing and Statistics | Data Cleaning |
| Data Processing and Statistics | Feature Engineering |
| Data Processing and Statistics | Data Visualization |
| Data Processing and Statistics | Train-Test Split |
| Data Processing and Statistics | Statistics Fundamentals |
| Data Processing and Statistics | Probabilistic Thinking |
| Data Processing and Statistics | Loss Functions and Gradients |
| Data Processing and Statistics | Overfitting, Underfitting, Bias and Variance |
| Supervised Learning | |
| Supervised Learning | Machine Learning Algorithms |
| Supervised Learning | Linear Regression |
| Supervised Learning | Multiple Linear Regression |
| Supervised Learning | Polynomial Regression |
| Supervised Learning | Logistic Regression |
| Supervised Learning | Regression Model Evaluation |
| Supervised Learning | Decision Tree |
| Supervised Learning | Support Vector Machine (SVM) |
| Supervised Learning | K-Nearest Neighbors (KNN) |
| Supervised Learning | Ensemble Learning |
| Supervised Learning | Naive Bayes |
| Supervised Learning | Random Forest |
| Supervised Learning | Classification Metrics |
| Unsupervised Learning | |
| Unsupervised Learning | Clustering |
| Unsupervised Learning | Dimensionality Reduction |
| Reinforcement Learning | |
| Reinforcement Learning | Basic Framework of Reinforcement Learning |
| Reinforcement Learning | Reinforcement Learning: Exploration vs. Exploitation |
| Reinforcement Learning | Reinforcement Learning: Q-Learning and SARSA |
| Reinforcement Learning | Deep Reinforcement Learning |
| Deep Learning | |
| Deep Learning | Basic Structure of Neural Networks |
| Deep Learning | Forward Propagation and Backpropagation |
| Deep Learning | Deep Learning vs. Traditional Machine Learning |
| Deep Learning | Common Network Types |
| Model Optimization and Engineering | |
| Model Optimization and Engineering | Cross-Validation |
| Model Optimization and Engineering | Regularization |
| Model Optimization and Engineering | Data Leakage |
| Model Optimization and Engineering | Ensemble Methods |
| Model Optimization and Engineering | Hyperparameter Search |
| Model Optimization and Engineering | MLOps Concepts |
| Model Optimization and Engineering | Common Troubleshooting |
| Machine Learning Limitations and Boundaries | |
| Machine Learning Limitations and Boundaries | Interpretability Issues |
| Machine Learning Limitations and Boundaries | Assumption Limitations |
| Machine Learning Limitations and Boundaries | Data Bias |
| Machine Learning Limitations and Boundaries | Real-World Cost of Models |
| Practical Cases | |
| Practical Cases | Titanic Survival Prediction |
| Practical Cases | House Price Prediction |
| Practical Cases | Customer Segmentation |
| Practical Cases | PCA Visualization |
| Practical Cases | Reinforcement Learning Example |
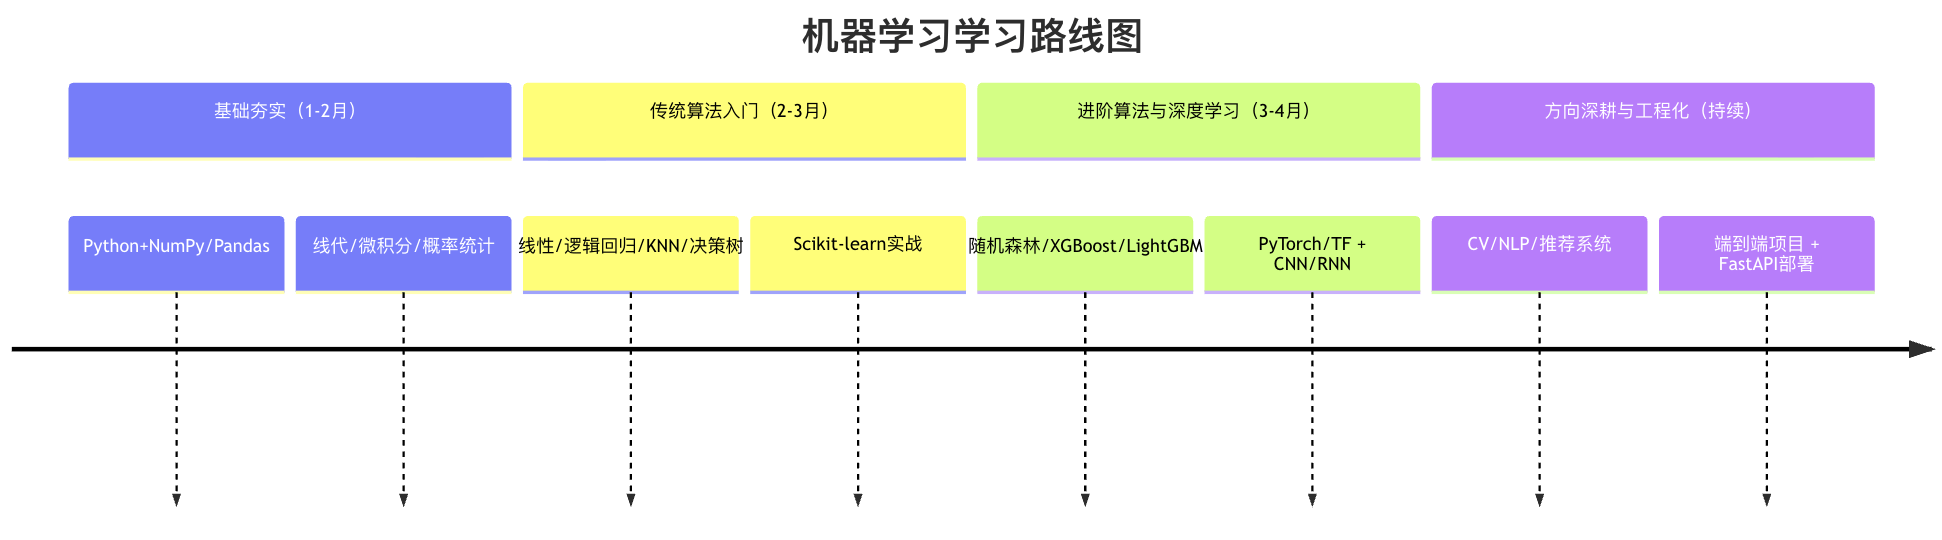
Phase 1: Foundation - Build a Solid Base
Before diving into complex algorithms, you need to first lay the foundation that supports the edifice of knowledge. The goal of this phase is to master the necessary mathematics, programming, and data analysis skills.
Core Skill 1: Programming Language (Python)
Python is the lingua franca of machine learning, favored for its clean syntax and rich ecosystem of libraries.
Learning Objectives: Master Python basic syntax, data structures, functions, and object-oriented programming.
Key Libraries:
NumPy: Used for efficient numerical computation; it is the foundation of nearly all scientific computing libraries.Pandas: Used for data cleaning, analysis, and processing; a powerful tool for manipulating data tables (DataFrames).Matplotlib/Seaborn: Used for data visualization to convert data into intuitive charts.
Next, we can look at an example.
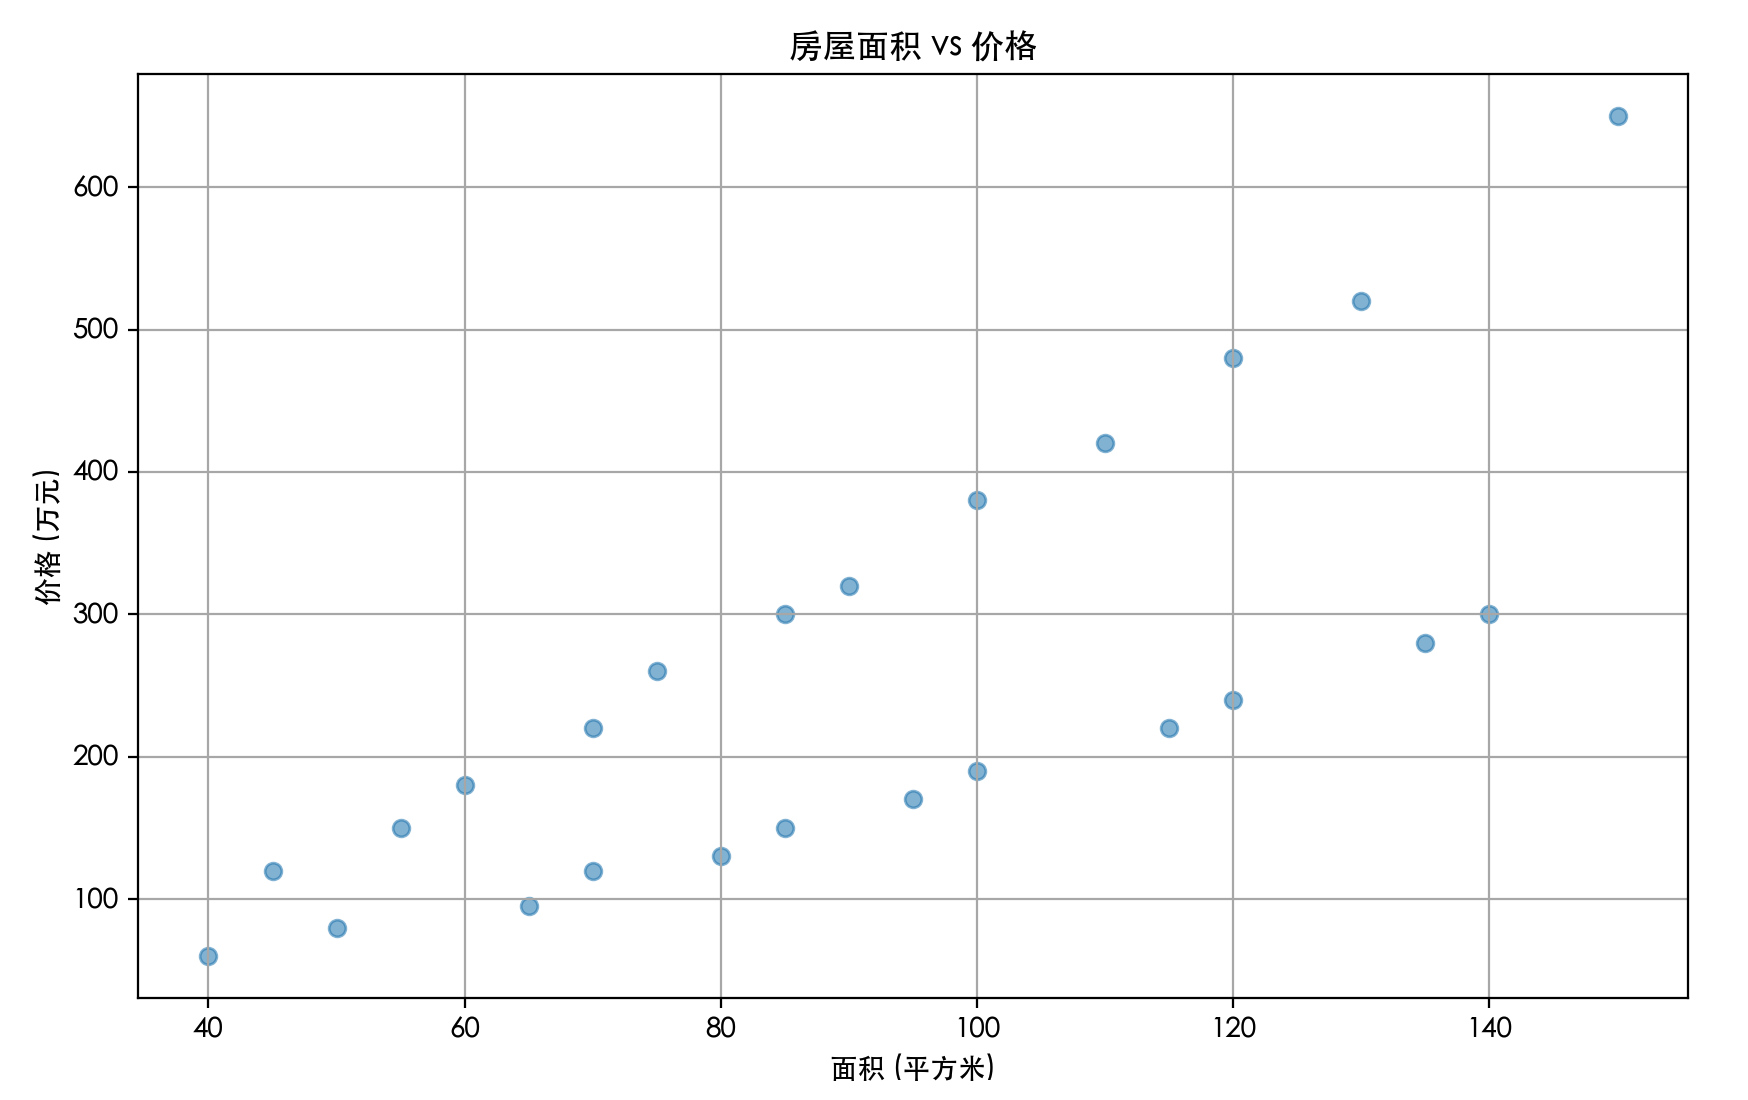
Test data house_prices.csv file content:
面积,价格,房龄,卧室数,城市
45,120,15,1,北京
60,180,12,2,北京
75,260,8,2,北京
90,320,6,3,北京
110,420,5,3,北京
130,520,3,4,北京
50,80,20,1,成都
70,120,15,2,成都
85,150,12,3,成都
100,190,10,3,成都
120,240,8,4,成都
140,300,5,4,成都
55,150,18,1,上海
70,220,14,2,上海
85,300,10,2,上海
100,380,8,3,上海
120,480,6,3,上海
150,650,4,4,上海
40,60,22,1,武汉
65,95,16,2,武汉
80,130,12,2,武汉
95,170,9,3,武汉
115,220,7,3,武汉
135,280,5,4,武汉
Example
import pandas as pd
import matplotlib.pyplot as plt
# -------------------------- Set Chinese font start --------------------------
plt.rcParams['font.sans-serif'] = [
# Windows first
'SimHei', 'Microsoft YaHei',
# macOS first
'PingFang SC', 'Heiti TC',
# Linux first
'WenQuanYi Micro Hei', 'DejaVu Sans'
]
# Fix the issue of negative signs displaying as squares
plt.rcParams['axes.unicode_minus'] = False
# -------------------------- Set Chinese font end --------------------------
# 1. Read data
data = pd.read_csv('house_prices.csv')
print("First 5 rows of data:")
print(data.head())
# 2. View basic data information
print("\nData info:")
print(data.info())
# 3. Plot a scatter plot of house area and price
plt.figure(figsize=(10, 6))
plt.scatter(data['Area'], data['Price'], alpha=0.5)
plt.title('House Area vs Price')
plt.xlabel('Area (square meters)')
plt.ylabel('Price (10,000 yuan)')
plt.grid(True)
plt.show()
"After execution, the output chart is as follows:"
Core Skill 2: Essential Mathematical Knowledge
You don't need to become a mathematician, but you need to understand the basic logic behind the algorithms.
- Linear Algebra: Understand vectors, matrices, and matrix multiplication. This is the foundation for understanding how data is represented and transformed in multidimensional space.
- Calculus: The focus is on understanding the concepts of derivatives and partial derivatives. They are the core of optimization algorithms (such as gradient descent) used to find the best parameters for a model.
- Probability and Statistics: Understand mean, variance, standard deviation, probability distributions, conditional probability, and Bayes' theorem. This is crucial for evaluating models and understanding uncertainty.
Analogy: Imagine a machine learning model as a complexmixing console. Mathematical knowledge is the manual that helps you understand how each knob (parameter) affects the final sound (prediction result). Without the manual, you can only fiddle blindly.
Phase 2: Getting Started - Master Classic Algorithms
With a solid foundation, you can begin to explore the core of machine learning—algorithms. It is recommended to start with the most classic and intuitive algorithms.
Introduction to Supervised Learning
Supervised learning means training models using data with existing labels.
- Linear Regression: Predict continuous values (e.g., house prices). Understand its cost function and gradient descent optimization process.
- Logistic Regression: Solves classification problems (e.g., determining whether an email is spam). Understand the Sigmoid function and decision boundary.
- K-Nearest Neighbors (K-NN): A simple instance-based classification/regression algorithm.
- Decision Tree: Simulates the human decision-making process, very intuitive and easy to understand.
Introduction to Unsupervised Learning
Unsupervised learning is used to discover intrinsic structures and patterns in data.
- K-Means Clustering: Automatically groups data into K clusters.
- Principal Component Analysis (PCA): Used for dimensionality reduction and visualization, extracting the most important features.
Tool Upgrade: At this stage, start systematically usingscikit-learnlibrary. It provides a unified API, allowing you to quickly implement, compare, and evaluate various algorithms.
Example
from sklearn.model_selection import train_test_split
from sklearn.linear_model import LogisticRegression
from sklearn.metrics import accuracy_score, classification_report
# =========================
# 1. Construct runnable test data
# Scenario: whether you pass the exam (1=pass, 0=fail)
# Features: study time, attendance rate, homework completion rate
# =========================
X = np.array([
[2, 60, 50],
[3, 65, 55],
[4, 70, 65],
[5, 75, 70],
[6, 80, 75],
[7, 85, 80],
[8, 90, 85],
[9, 92, 88],
[10, 95, 90],
[11, 97, 92],
[1, 50, 40],
[2, 55, 45],
[3, 60, 50],
[4, 65, 55],
[5, 70, 60],
[6, 75, 65],
[7, 80, 70],
[8, 85, 75],
[9, 90, 80],
[10, 95, 85]
])
y = np.array([
0, 0, 0, 0, 1,
1, 1, 1, 1, 1,
0, 0, 0, 0, 0,
1, 1, 1, 1, 1
])
# =========================
# 2. Split the data into training and test sets
# =========================
X_train, X_test, y_train, y_test = train_test_split(
X, y, test_size=0.3, random_state=42
)
# =========================
# 3. Create and train the model
# =========================
model = LogisticRegression(max_iter=1000)
model.fit(X_train, y_train)
# =========================
# 4. Make predictions
# =========================
y_pred = model.predict(X_test)
# =========================
# 5. Evaluate model performance
# =========================
print(f"Model accuracy: {accuracy_score(y_test, y_pred):.2f}")
print("\nDetailed classification report:")
print(classification_report(y_test, y_pred))
Output:
模型准确率:0.83

详细分类报告:
              precision    recall  f1-score   support

           0       0.67      1.00      0.80         2
           1       1.00      0.75      0.86         4

    accuracy                           0.83         6
   macro avg       0.83      0.88      0.83         6
weighted avg       0.89      0.83      0.84         6
Phase 3: Advanced - Dive into Core Areas
After mastering classic algorithms, you can move toward more modern and powerful areas.
Deep Dive into Traditional Machine Learning
- Ensemble Learning: Learn how to combine multiple weak models to build a strong model.
- Random Forest: An ensemble of multiple decision trees, with strong resistance to overfitting.
- Gradient Boosting Trees (e.g., XGBoost, LightGBM): Highly performant algorithms extremely popular in competitions and industry.
- Support Vector Machine (SVM): Understand its core idea of maximizing the "margin".
- Model Evaluation and Optimization: Dive deep into cross-validation, hyperparameter tuning (e.g., GridSearchCV), and methods for solving overfitting/underfitting.
Step into Deep Learning
When data (especially images, text, and speech) becomes complex, deep learning begins to demonstrate its powerful capabilities.
- Neural Network Basics: Understand neurons, activation functions, forward propagation, backpropagation, and loss functions.
- Deep Learning Frameworks: Choose
PyTorch(research-friendly, flexible) orTensorFlow/Keras(mature production environment, complete ecosystem), and study one of them in depth. - Convolutional Neural Network (CNN): The standard for processing image data; understand the roles of convolutional layers and pooling layers.
- Recurrent Neural Network (RNN) and Long Short-Term Memory Network (LSTM): Powerful tools for processing sequence data (e.g., text, time series).
Example
from tensorflow import keras
from tensorflow.keras import layers
model = keras.Sequential([
layers.Dense(64, activation='relu', input_shape=(input_dim,)), # Hidden layer 1
layers.Dropout(0.2), # Dropout layer, to prevent overfitting
layers.Dense(32, activation='relu'), # Hidden layer 2
layers.Dense(1, activation='sigmoid') # Output layer, for binary classification
])
model.compile(optimizer='adam',
loss='binary_crossentropy',
metrics=['accuracy'])
model.summary() # Print model structure
# After that, you can use model.fit for training
Phase 4: Application and Expansion - Focus on Directions, Solve Real-World Problems
Machine learning has many branches; at this point you need to choose a direction to go deep into based on your interests or career plans.
Major Direction Selection
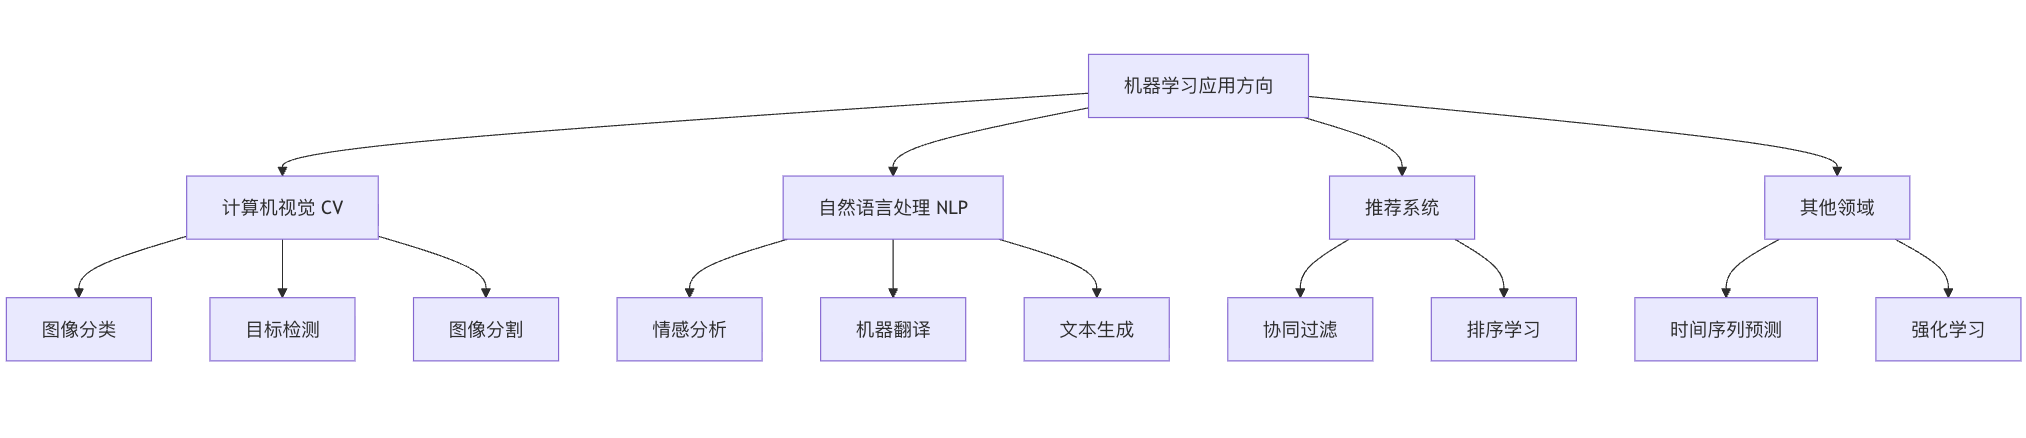
- Computer Vision (CV): Deep dive into CNN variants (ResNet, YOLO), learn image segmentation and object detection.
- Natural Language Processing (NLP): Learn from word embeddings (Word2Vec) to the Transformer architecture (BERT, GPT), mastering text classification, sentiment analysis, and machine translation.
- Recommendation Systems: Learn collaborative filtering, matrix factorization, and deep learning recommendation models.
- Reinforcement Learning: Enables an agent to learn optimal policies by interacting with the environment; it is the core of game AI and robot control.
Engineering and Deployment
Learn how to deploy trained models to production environments and provide real services.
- Model Saving and Loading(
pickle,joblib,.h5file). - Use Flask/FastAPI to build a simple API service。
- Understand Docker containerizationand the basic concepts of cloud services (e.g., AWS SageMaker, Google AI Platform).
Summary and Resource Recommendations
Learning Path Visualization
Practice is the Only Shortcut
The Most Important Advice:Learn by doing, project-driven!
- Imitate: Reproduce projects from tutorials and papers.
- Practice: Participate in beginner-level competitions on platforms like Kaggle and Tianchi.
- Create: Try to use machine learning to solve a small problem you are personally interested in (e.g., analyzing your exercise data, automatically classifying your photo collection).
Quality Resource Recommendations
- Classic Courses: Andrew Ng's "Machine Learning" (Coursera), Mu Li's "Dive into Deep Learning".
- Practice Platforms: Kaggle (competitions and datasets), Colab / Jupyter Notebook (free cloud environment).
- Knowledge Consolidation: Read
scikit-learn、PyTorchofficial documentation, and communicate on Stack Overflow and related forum communities.