Python Machine Learning Libraries
This chapter will introduce you to the four core Python libraries in machine learning: NumPy, Pandas, Matplotlib, and Scikit-learn.
Machine learning libraries are like a professional toolbox, and each library has a specific purpose; when used together, they can accomplish complex machine learning tasks.
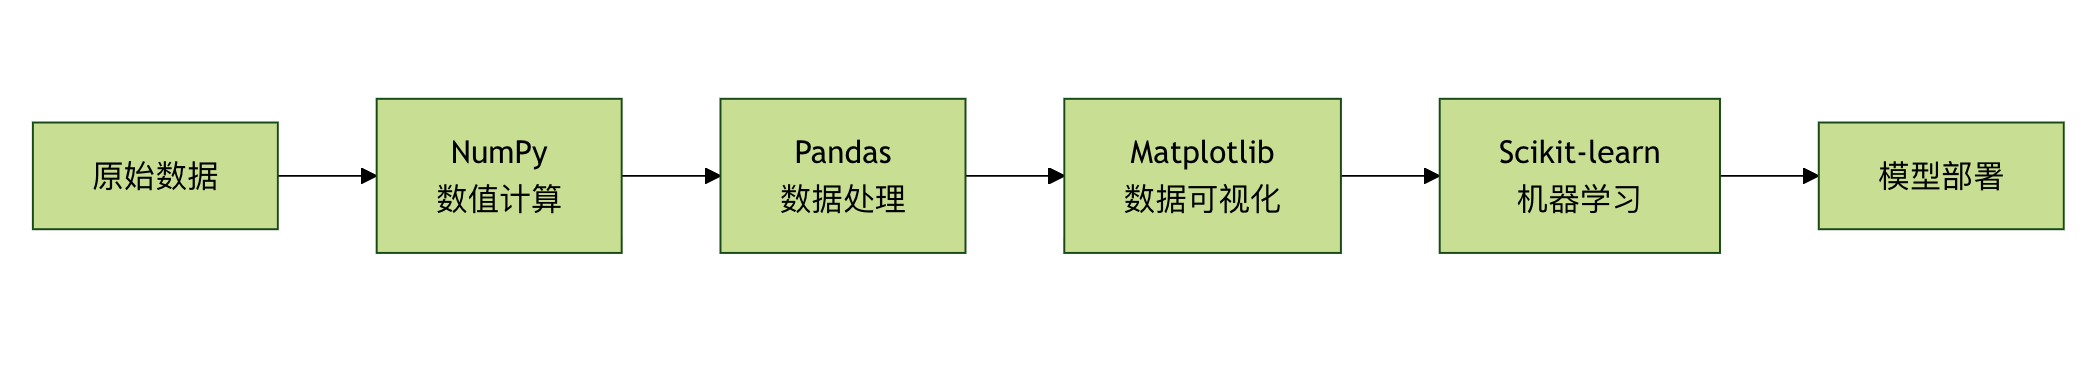
Roles of the Four Core Libraries
- Numpy: the foundation of numerical computation, providing efficient array operations
- Pandas: the sharp tool for data processing, providing data structures and analysis tools
- Matplotlib: the brush for data visualization, creating various charts
- scikit-learn: the Swiss Army knife of machine learning, providing a complete ML toolchain
NumPy: The Foundation of Numerical Computation
What is NumPy?
NumPy is like a calculator for mathematical computation, but it is countless times more powerful. It is the foundational library for scientific computing in Python, providing efficient multi-dimensional array objects.
Core Concepts of NumPy
1. Array
Example
import numpy as np
# Different ways to create arrays
print("=== NumPy Array Creation ===")
# Create from a list
arr1 = np.array([1, 2, 3, 4, 5])
print(f"Created from list: {arr1}")
# Create an arithmetic sequence array
arr2 = np.arange(0, 10, 2) # 0 to 10, step size 2
print(f"Arithmetic sequence array: {arr2}")
# Create an evenly spaced array
arr3 = np.linspace(0, 1, 5) # 0 to 1, 5 points
print(f"Evenly spaced array: {arr3}")
# Create special arrays
zeros_arr = np.zeros((2, 3)) # 2x3 array of zeros
ones_arr = np.ones((2, 3)) # 2x3 array of ones
identity_arr = np.eye(3) # 3x3 identity matrix
print(f"Zero array:\n{zeros_arr}")
print(f"Ones array:\n{ones_arr}")
print(f"Identity matrix:\n{identity_arr}")
2. Array Operations
Example
print("\n=== Array Basic Operations ===)
# Array attributes
arr = np.array([[1, 2, 3], [4, 5, 6]])
print(f"Array:"\n{arr}")
print(f"Shape: {arr.shape}")
print(f"Dimension: {arr.ndim}")
print(f"Number of elements: {arr.size}")
print(f"Data type: {arr.dtype}")
# Array indexing and slicing
print(f"First row: {arr)
print(f"First column: {arr[:, 0]}")
print(f"Element [1,2]: {arr[1, 2]}")
# Array operations
arr1 = np.array([1, 2, 3])
arr2 = np.array([4, 5, 6])
print(f"Addition: {arr1 + arr2}")
print(f"Multiplication: {arr1 * arr2}")
print(f"Dot product: {np.dot(arr1, arr2)}")
# Statistical functions
data = np.array([1, 2, 3, 4, 5, 6, 7, 8, 9, 10])
print(f"Mean: {np.mean(data)}")
print(f"Standard deviation: {np.std(data)}")
print(f"Maximum: {np.max(data)}")
print(f"Minimum: {np.min(data)}")
print(f"Median: {np.median(data)}")
NumPy Practical Application Example
Example
def numpy_linear_regression():
"""Implement simple linear regression using NumPy"""
# Generate sample data
np.random.seed(42)
X = 2 * np.random.rand(100, 1) # Features
y = 4 + 3 * X + np.random.randn(100, 1) # Labels + noise
# Add x0 = 1 to X
X_b = np.c_[np.ones((100, 1)), X] # Add bias term
# Solve using the normal equation: θ = (X^T * X)^(-1) * X^T * y
theta_best = np.linalg.inv(X_b.T.dot(X_b)).dot(X_b.T).dot(y)
print("=== NumPy Linear Regression Example ===")
print(f"Learned parameters: intercept={theta_best)
# Prediction
X_new = np.array([[0], [2]])
X_new_b = np.c_[np.ones((2, 1)), X_new]
y_predict = X_new_b.dot(theta_best)
print(f"Prediction results: y={y_predict)
return theta_best, X, y
# Run the example
theta, X, y = numpy_linear_regression()
Pandas: The Sharp Tool for Data Processing
What is Pandas?
Pandas is like the Swiss Army knife of data processing, providing powerful data structures and data analysis tools, especially suitable for handling tabular data.
Core Data Structures of Pandas
1. Series (One-Dimensional Data)
Example
import pandas as pd
print("=== Pandas Series ===")
# Create a Series from a list
s1 = pd.Series([1, 2, 3, 4, 5])
print(f"Created from list:\n{s1}")
# Series with index
s2 = pd.Series([10, 20, 30], index=['a', 'b', 'c'])
print(f"\nSeries with index:\n{s2}")
# Create a Series from a dictionary
s3 = pd.Series({'Math': 90, 'English': 85, 'Physics': 88})
print(f"\nCreated from dictionary:\n{s3}")
# Series operations
print(f"\nAccess element: s2['b'] = {s2['b']}")
print(f"Slicing: s2[0:2] =\n{s2[0:2]}")
print(f"Statistical information:\n{s2.describe()}")
2. DataFrame (Two-Dimensional Data)
Example
print("\n=== Pandas DataFrame ===")
# Create a DataFrame
data = {
'Name': ['Zhang San', 'Li Si', 'Wang Wu', 'Zhao Liu'],
'Age': [25, 30, 35, 28],
'City': ['Beijing', 'Shanghai', 'Guangzhou', 'Shenzhen'],
'Salary': [15000, 20000, 18000, 22000]
}
df = pd.DataFrame(data)
print("Original DataFrame:")
print(df)
# DataFrame basic operations
print(f"\nDataFrame shape: {df.shape}")
print(f"\nColumn names: {list(df.columns)}")
print(f"\nData types:\n{df.dtypes}")
# Select data
print(f"\nSelect the 'Name' column:\n{df['Name']}")
print(f"\nSelect the first two rows:\n{df.head(2)}")
print(f"\nSelect rows where age is greater than 28:\n{df[df['Age'] > 28]}")
# Statistical information
print(f"\nStatistical information for numeric columns:\n{df.describe()}")
# Add a new column
df['Annual Salary'] = df['Salary'] * 12
print(f"\nAfter adding the annual salary column:\n{df}")
Pandas Data Processing Example
Example
def pandas_data_processing():
"""Demonstrate the complete workflow of Pandas data processing"""
print("=== Pandas Data Processing Example ===")
# 1. Create sample data
np.random.seed(42)
n_samples = 1000
data = {
'Student ID': range(1, n_samples + 1),
'Name': [f'Student {i}' for i in range(1, n_samples + 1)],
'Age': np.random.randint(18, 25, n_samples),
'Gender': np.random.choice(['Male', 'Female'], n_samples),
'Math Score': np.random.normal(75, 15, n_samples),
'English Score': np.random.normal(80, 12, n_samples),
'Physics Score': np.random.normal(72, 18, n_samples),
'Class': np.random.choice(['Class 1', 'Class 2', 'Class 3'], n_samples)
}
df = pd.DataFrame(data)
# 2. Data Cleaning
print("Original data shape:", df.shape)
# Handle outliers (scores should be between 0-100)
score_columns = ['Math Score', 'English Score', 'Physics Score']
for col in score_columns:
df[col] = df[col].clip(0, 100)
# 3. Feature Engineering
# Calculate total score and average score
df['Total Score'] = df[score_columns].sum(axis=1)
df['Average Score'] = df[score_columns].mean(axis=1)
# Add grade
def get_grade(score):
if score >= 90:
return 'A'
elif score >= 80:
return 'B'
elif score >= 70:
return 'C'
elif score >= 60:
return 'D'
else:
return 'F'
df['Grade'] = df['Average Score'].apply(get_grade)
# 4. Data Analysis
print("\n=== Data Analysis Results ===)
# Basic statistics
print("Average scores by subject:")
print(df[score_columns].mean())
# Analyze by class
print("\nAverage score by class:")
class_avg = df.groupby('Class')['Average Score'].mean()
print(class_avg)
# Analyze by gender
print("\nGender distribution:")
gender_count = df['Gender'].value_counts()
print(gender_count)
# Grade distribution
print("\nGrade distribution:")
grade_dist = df['Grade'].value_counts().sort_index()
print(grade_dist)
# 5. Data Filtering
print("\n=== Specific Data Filtering ===)
# Excellent students (average score > 85)
excellent_students = df[df['Average Score'] > 85].head(5)
print("Excellent students (Top 5):")
print(excellent_students[['Name', 'Average Score', 'Grade']])
# Top-scoring student in each class
print("\nTop-scoring student in each class:")
top_students = df.loc[df.groupby('Class')['Average Score'].idxmax()]
print(top_students[['Class', 'Name', 'Average Score']])
return df
# Run example
student_df = pandas_data_processing()
Matplotlib: The Brush for Data Visualization
What is Matplotlib?
Matplotlib is like a data artist's paintbrush, which can convert dull data into intuitive charts, helping us understand patterns and relationships in the data.
Basic Charts in Matplotlib
Example
import matplotlib.pyplot as plt
import numpy as np
# Set Chinese font (prevent Chinese characters from displaying as boxes)
plt.rcParams['font.sans-serif'] = ['SimHei', 'Arial Unicode MS']
plt.rcParams['axes.unicode_minus'] = False
def matplotlib_basic_charts():
"""Demonstrate Matplotlib basic charts"""
print("=== Matplotlib Basic Chart Example ===")
# 1. Line chart
plt.figure(figsize=(12, 8))
plt.subplot(2, 3, 1)
x = np.linspace(0, 10, 100)
y1 = np.sin(x)
y2 = np.cos(x)
plt.plot(x, y1, label='sin(x)')
plt.plot(x, y2, label='cos(x)')
plt.title('Trigonometric functions')
plt.xlabel('x')
plt.ylabel('y')
plt.legend()
plt.grid(True)
# 2. Scatter plot
plt.subplot(2, 3, 2)
np.random.seed(42)
x = np.random.randn(100)
y = 2 * x + np.random.randn(100) * 0.5
plt.scatter(x, y, alpha=0.6, c='blue')
plt.title('Scatter plot')
plt.xlabel('X')
plt.ylabel('Y')
# 3. Bar chart
plt.subplot(2, 3, 3)
categories = ['A', 'B', 'C', 'D', 'E']
values = [23, 45, 56, 78, 32]
plt.bar(categories, values, color=['red', 'green', 'blue', 'orange', 'purple'])
plt.title('Bar chart')
plt.xlabel('Category')
plt.ylabel('Value')
# 4. Histogram
plt.subplot(2, 3, 4)
data = np.random.normal(100, 15, 1000)
plt.hist(data, bins=30, alpha=0.7, color='skyblue', edgecolor='black')
plt.title('Histogram')
plt.xlabel('Value')
plt.ylabel('Frequency')
# 5. Pie chart
plt.subplot(2, 3, 5)
sizes = [30, 25, 20, 15, 10]
labels = ['A', 'B', 'C', 'D', 'E']
colors = ['gold', 'lightcoral', 'lightskyblue', 'lightgreen', 'plum']
plt.pie(sizes, labels=labels, colors=colors, autopct='%1.1f%%', startangle=90)
plt.title('Pie chart')
# 6. Box plot
plt.subplot(2, 3, 6)
data1 = np.random.normal(0, 1, 100)
data2 = np.random.normal(2, 1, 100)
data3 = np.random.normal(-2, 1, 100)
plt.boxplot([data1, data2, data3], labels=['Group 1', 'Group 2', 'Group 3'])
plt.title('Box plot')
plt.ylabel('Value')
plt.tight_layout()
plt.show()
print("Chart displayed!")
# Run example
matplotlib_basic_charts()
Advanced Visualization Example
Example
def advanced_visualization():
"""Demonstrate advanced visualization techniques"""
print("=== Advanced Visualization Example ===")
# Create more complex data
np.random.seed(42)
n_points = 200
# Generate correlated data
x = np.random.randn(n_points)
y = 2 * x + np.random.randn(n_points) * 0.5
colors = np.random.rand(n_points)
sizes = 1000 * np.random.rand(n_points)
# 1. Bubble chart
plt.figure(figsize=(15, 5))
plt.subplot(1, 3, 1)
scatter = plt.scatter(x, y, c=colors, s=sizes, alpha=0.6, cmap='viridis')
plt.colorbar(scatter, label='Color value')
plt.title('Bubble chart')
plt.xlabel('X')
plt.ylabel('Y')
# 2. Heatmap
plt.subplot(1, 3, 2)
data = np.random.randn(10, 10)
im = plt.imshow(data, cmap='coolwarm', aspect='auto')
plt.colorbar(im, label='Value')
plt.title('Heatmap')
# 3. Subplot combination
plt.subplot(1, 3, 3)
# Create subplots
gs = plt.GridSpec(2, 2, subplot_kw={'projection': 'polar'})
ax1 = plt.subplot(gs[0, 0])
theta = np.linspace(0, 2*np.pi, 100)
r = np.sin(3*theta)
ax1.plot(theta, r)
ax1.set_title('Polar chart')
ax2 = plt.subplot(gs[0, 1])
categories = ['A', 'B', 'C', 'D']
values = [15, 30, 45, 10]
ax2.bar(categories, values)
ax2.set_title('Bar chart')
ax3 = plt.subplot(gs[1, :])
x_line = np.linspace(0, 10, 100)
y_line1 = np.sin(x_line)
y_line2 = np.cos(x_line)
ax3.plot(x_line, y_line1, label='sin')
ax3.plot(x_line, y_line2, label='cos')
ax3.set_title('Combined chart')
ax3.legend()
plt.tight_layout()
plt.show()
print("Advanced chart displayed!")
# Run example
advanced_visualization()
Scikit-learn: The Swiss Army Knife of Machine Learning
What is Scikit-learn?
Scikit-learn is like a toolbox for machine learning, providing a complete toolchain from data preprocessing to model training and evaluation, and is the de facto standard for Python machine learning.
Core Features of Scikit-learn
Example
from sklearn.datasets import make_classification, load_iris
from sklearn.model_selection import train_test_split
from sklearn.preprocessing import StandardScaler, LabelEncoder
from sklearn.linear_model import LogisticRegression
from sklearn.ensemble import RandomForestClassifier
from sklearn.svm import SVC
from sklearn.metrics import accuracy_score, classification_report, confusion_matrix
def scikit_learn_basics():
"""Demonstrate the core functionality of Scikit-learn"""
print("=== Scikit-learn Core Functionality Example ===")
# 1. Data generation
X, y = make_classification(
n_samples=1000,
n_features=20,
n_classes=3,
n_informative=15,
random_state=42
)
print(f"Data shape: X={X.shape}, y={y.shape}")
print(f"Class distribution: {np.bincount(y)}")
# 2. Data splitting
X_train, X_test, y_train, y_test = train_test_split(
X, y, test_size=0.2, random_state=42, stratify=y
)
print(f"Training set size: {X_train.shape)
print(f"Test set size: {X_test.shape)
# 3. Data preprocessing
scaler = StandardScaler()
X_train_scaled = scaler.fit_transform(X_train)
X_test_scaled = scaler.transform(X_test)
print("Data standardization complete")
# 4. Model training and comparison
models = {
'Logistic Regression': LogisticRegression(random_state=42),
'Random Forest': RandomForestClassifier(n_estimators=100, random_state=42),
'Support Vector Machine': SVC(random_state=42)
}
results = {}
for name, model in models.items():
print(f"\nTraining {name}...")
# Train model
model.fit(X_train_scaled, y_train)
# Predict
y_pred = model.predict(X_test_scaled)
# Evaluate
accuracy = accuracy_score(y_test, y_pred)
results[name] = accuracy
print(f"{name} Accuracy: {accuracy:.4f}")
print(f"Classification report:\n{classification_report(y_test, y_pred)}")
# 5. Result comparison
print("\n=== Model Comparison === ")
for name, accuracy in results.items():
print(f"{name}: {accuracy:.4f}")
best_model = max(results, key=results.get)
print(f"\nBest model: {best_model}")
return models[best_model]
# Run example
best_model = scikit_learn_basics()
Complete Machine Learning Workflow
Example
def complete_ml_pipeline():
"""Demonstrate the complete machine learning workflow"""
print("=== Complete Machine Learning Workflow ===")
# 1. Load data
iris = load_iris()
X = iris.data
y = iris.target
feature_names = iris.feature_names
target_names = iris.target_names
print(f"Dataset: {iris.DESCR.split('\n')[0]}")
print(f"Number of features: {len(feature_names)}")
print(f"Number of classes: {len(target_names)}")
# 2. Data exploration
df = pd.DataFrame(X, columns=feature_names)
df['target'] = y
print("\nData preview:")
print(df.head())
print("\nData statistics:")
print(df.describe())
# 3. Data visualization
plt.figure(figsize=(12, 4))
plt.subplot(1, 2, 1)
for i, target_name in enumerate(target_names):
plt.scatter(
df[df['target'] == i]['sepal length (cm)'],
df[df['target'] == i]['sepal width (cm)'],
label=target_name
)
plt.xlabel('Sepal length')
plt.ylabel('Sepal width')
plt.title('Sepal size distribution')
plt.legend()
plt.subplot(1, 2, 2)
for i, target_name in enumerate(target_names):
plt.scatter(
df[df['target'] == i]['petal length (cm)'],
df[df['target'] == i]['petal width (cm)'],
label=target_name
)
plt.xlabel('Petal length')
plt.ylabel('Petal width')
plt.title('Petal size distribution')
plt.legend()
plt.tight_layout()
plt.show()
# 4. Data preparation
X_train, X_test, y_train, y_test = train_test_split(
X, y, test_size=0.3, random_state=42, stratify=y
)
# 5. Model training
from sklearn.ensemble import RandomForestClassifier
model = RandomForestClassifier(n_estimators=100, random_state=42)
model.fit(X_train, y_train)
# 6. Model evaluation
y_pred = model.predict(X_test)
accuracy = accuracy_score(y_test, y_pred)
print(f"\nModel accuracy: {accuracy:.4f}")
print("\nConfusion matrix:")
print(confusion_matrix(y_test, y_pred))
print("\nClassification report:")
print(classification_report(y_test, y_pred, target_names=target_names))
# 7. Feature importance
feature_importance = model.feature_importances_
feature_df = pd.DataFrame({
'Feature': feature_names,
'Importance': feature_importance
}).sort_values('Importance', ascending=False)
print("\nFeature importance:")
print(feature_df)
# 8. Feature importance visualization
plt.figure(figsize=(8, 4))
plt.bar(feature_df['Feature'], feature_df['Importance'])
plt.title('Feature importance')
plt.xlabel('Feature')
plt.ylabel('Importance')
plt.xticks(rotation=45)
plt.tight_layout()
plt.show()
return model, feature_df
# Run example
trained_model, feature_importance = complete_ml_pipeline()
Example of the Four Libraries Working Together
Example
def four_libraries_integration():
"""Demonstrate the collaboration of NumPy, Pandas, Matplotlib, and Scikit-learn"""
print("=== Four-Library Collaboration Example ===")
# 1. NumPy: Generate simulated data
np.random.seed(42)
n_samples = 500
# Generate features
study_hours = np.random.uniform(1, 10, n_samples) # Study time
sleep_hours = np.random.uniform(5, 9, n_samples) # Sleep time
practice_tests = np.random.randint(0, 20, n_samples) # Number of practice questions
# Generate labels (exam scores), based on a linear combination of features plus noise
exam_scores = (
5 * study_hours +
3 * sleep_hours +
2 * practice_tests +
np.random.normal(0, 10, n_samples)
)
# Ensure scores are in the range 0-100
exam_scores = np.clip(exam_scores, 0, 100)
# 2. Pandas: Create a DataFrame and perform data processing
df = pd.DataFrame({
'Study Time': study_hours,
'Sleep Time': sleep_hours,
'Number of Practice Questions': practice_tests,
'Exam Score': exam_scores
})
# Add grade column
df['Grade'] = pd.cut(df['Exam Score'],
bins=[0, 60, 70, 80, 90, 100],
labels=['F', 'D', 'C', 'B', 'A'])
print("Data preview:")
print(df.head())
print(f"\nData shape: {df.shape}")
print(f"\nGrade Distribution:")
print(df['Grade'].value_counts().sort_index())
# 3. Matplotlib: Data Visualization
plt.figure(figsize=(15, 10))
# Subplot 1: Feature Distribution
plt.subplot(2, 3, 1)
df[['Study Time', 'Sleep Duration', 'Number of Practice Problems']].hist(bins=20, ax=plt.gca())
plt.title('Feature Distribution')
# Subplot 2: Score Distribution
plt.subplot(2, 3, 2)
plt.hist(df['Exam Score'], bins=20, alpha=0.7, color='skyblue')
plt.title('Exam Score Distribution')
plt.xlabel('Score')
plt.ylabel('Frequency')
# Subplot 3: Study Time vs Score
plt.subplot(2, 3, 3)
plt.scatter(df['Study Time'], df['Exam Score'], alpha=0.6)
plt.xlabel('Study Time')
plt.ylabel('Exam Score')
plt.title('Relationship Between Study Time and Score')
# Subplot 4: Sleep Duration vs Score
plt.subplot(2, 3, 4)
plt.scatter(df['Sleep Duration'], df['Exam Score'], alpha=0.6, color='orange')
plt.xlabel('Sleep Duration')
plt.ylabel('Exam Score')
plt.title('Relationship Between Sleep Duration and Score')
# Subplot 5: Number of Practice Problems vs Score
plt.subplot(2, 3, 5)
plt.scatter(df['Number of Practice Problems'], df['Exam Score'], alpha=0.6, color='green')
plt.xlabel('Number of Practice Problems')
plt.ylabel('Exam Score')
plt.title('Relationship Between Practice Problems and Score')
# Subplot 6: Grade Distribution Pie Chart
plt.subplot(2, 3, 6)
grade_counts = df['Grade'].value_counts()
plt.pie(grade_counts.values, labels=grade_counts.index, autopct='%1.1f%%')
plt.title('Grade Distribution')
plt.tight_layout()
plt.show()
# 4. Scikit-learn: Machine Learning Modeling
from sklearn.linear_model import LinearRegression
from sklearn.ensemble import RandomForestRegressor
from sklearn.metrics import mean_squared_error, r2_score
# Prepare Data
X = df[['Study Time', 'Sleep Duration', 'Number of Practice Problems']]
y = df['Exam Score']
X_train, X_test, y_train, y_test = train_test_split(
X, y, test_size=0.2, random_state=42
)
# Train Linear Regression Model
lr_model = LinearRegression()
lr_model.fit(X_train, y_train)
lr_pred = lr_model.predict(X_test)
lr_mse = mean_squared_error(y_test, lr_pred)
lr_r2 = r2_score(y_test, lr_pred)
# Train Random Forest Model
rf_model = RandomForestRegressor(n_estimators=100, random_state=42)
rf_model.fit(X_train, y_train)
rf_pred = rf_model.predict(X_test)
rf_mse = mean_squared_error(y_test, rf_pred)
rf_r2 = r2_score(y_test, rf_pred)
# Model Comparison
print("\n=== Model Comparison ===")
print(f"Linear Regression: MSE={lr_mse:.2f}, R²={lr_r2:.4f}")
print(f"Random Forest: MSE={rf_mse:.2f}, R²={rf_r2:.4f}")
# Linear Regression Coefficients
print(f"\nLinear Regression Coefficients:")
for feature, coef in zip(X.columns, lr_model.coef_):
print(f"{feature}: {coef:.2f}")
# Random Forest Feature Importance
print(f"\nRandom Forest Feature Importance:")
for feature, importance in zip(X.columns, rf_model.feature_importances_):
print(f"{feature}: {importance:.4f}")
# Prediction Results Visualization
plt.figure(figsize=(12, 5))
plt.subplot(1, 2, 1)
plt.scatter(y_test, lr_pred, alpha=0.6)
plt.plot([y_test.min(), y_test.max()], [y_test.min(), y_test.max()], 'r--')
plt.xlabel('True Score')
plt.ylabel('Predicted Score')
plt.title('Linear Regression Prediction Results')
plt.subplot(1, 2, 2)
plt.scatter(y_test, rf_pred, alpha=0.6)
plt.plot([y_test.min(), y_test.max()], [y_test.min(), y_test.max()], 'r--')
plt.xlabel('True Score')
plt.ylabel('Predicted Score')
plt.title('Random Forest Prediction Results')
plt.tight_layout()
plt.show()
return {
'data': df,
'linear_model': lr_model,
'rf_model': rf_model,
'linear_metrics': {'mse': lr_mse, 'r2': lr_r2},
'rf_metrics': {'mse': rf_mse, 'r2': rf_r2}
}
# Run Complete Example
results = four_libraries_integration()