Ollama Tutorial
Ollama is an open-source local large language model runtime framework, designed for conveniently deploying and running large language models (LLMs) on local machines.
Ollama supports multiple operating systems, including macOS, Windows, Linux, and running via Docker containers.
Simply put, if services like ChatGPT, Claude, and DeepSeeek call models hosted by others over the internet, Ollama is more like alocal AI model runtime environment.。
Who is this tutorial for?
Ollama is suitable for developers, researchers, and users with high data privacy requirements. It helps users quickly deploy and run large language models in a local environment, while also providing flexible customization options.
With Ollama, we can run qwen3.5, Llama 3.3, DeepSeek-R1, Phi-4, Mistral, Gemma 2, and other models locally.
| User Type | What they might want to do |
|---|---|
| AI beginners | Understand what local large models are, install Ollama, download, run, and delete models |
| Programmers / Developers | Integrate large models into their own Python, JavaScript, and Web applications |
| AI Agent developers | Connect local models to programming agents such as Claude Code, Codex, and OpenCode |
| Ordinary users who want to experience local AI | No API purchases, no cloud data uploads, experience various open-source models on their own computers |
What can developers do with Ollama?
For developers, the value of Ollama lies in turning large models into a local service that can be called at any time.
Typical uses include: AI chatbots, AI writing tools, AI coding assistants, document analysis tools, RAG knowledge bases, vector retrieval, AI agents, automated workflows, and local AI web applications.
Behind these capabilities are Ollama's interfaces for text generation, chat, model management, embedding, and more, with support for streaming responses and tool calling.
Why do Agent developers need it?
If you are learning AI programming tools such as Claude Code, Codex, and OpenCode, Ollama can serve as their local model backend.
Ollama already provides official integration with tools such as Claude Code, Codex, OpenCode, Copilot CLI, Droid, etc., with a singleollama launchcommand to connect local models to these Agent workflows. This will be detailed in the integration chapter.
What you need to know before starting this tutorial
Ollama itself is not difficult. If you just want to run models, you basically don't need a programming background.
Different learning goals correspond to different baseline requirements. You can use the table below to assess your starting point:
| Learning Goal | Prerequisites |
|---|---|
| Install Ollama | Basic computer skills, terminal basics |
| Download and run models | Basic command-line knowledge |
| Use Ollama API | HTTP, JSON basics |
| Python development | Python 3.x basics |
| JavaScript development | JavaScript / TypeScript basics |
| RAG / Agent development | Python + large model basics |
| Model deployment and optimization | GPU, VRAM, Linux, Docker basics, etc. |
If you just want to experience Ollama, knowing what a terminal, command, folder, and model are is basically enough.
If you want to further develop AI applications, it is recommended to first understand HTTP / REST API, JSON, Python or JavaScript, and the basic usage of Git and Docker.
Create New Models
This is Ollama's core capability: run open-source models on your own computer or server without having to set up a complex inference environment.
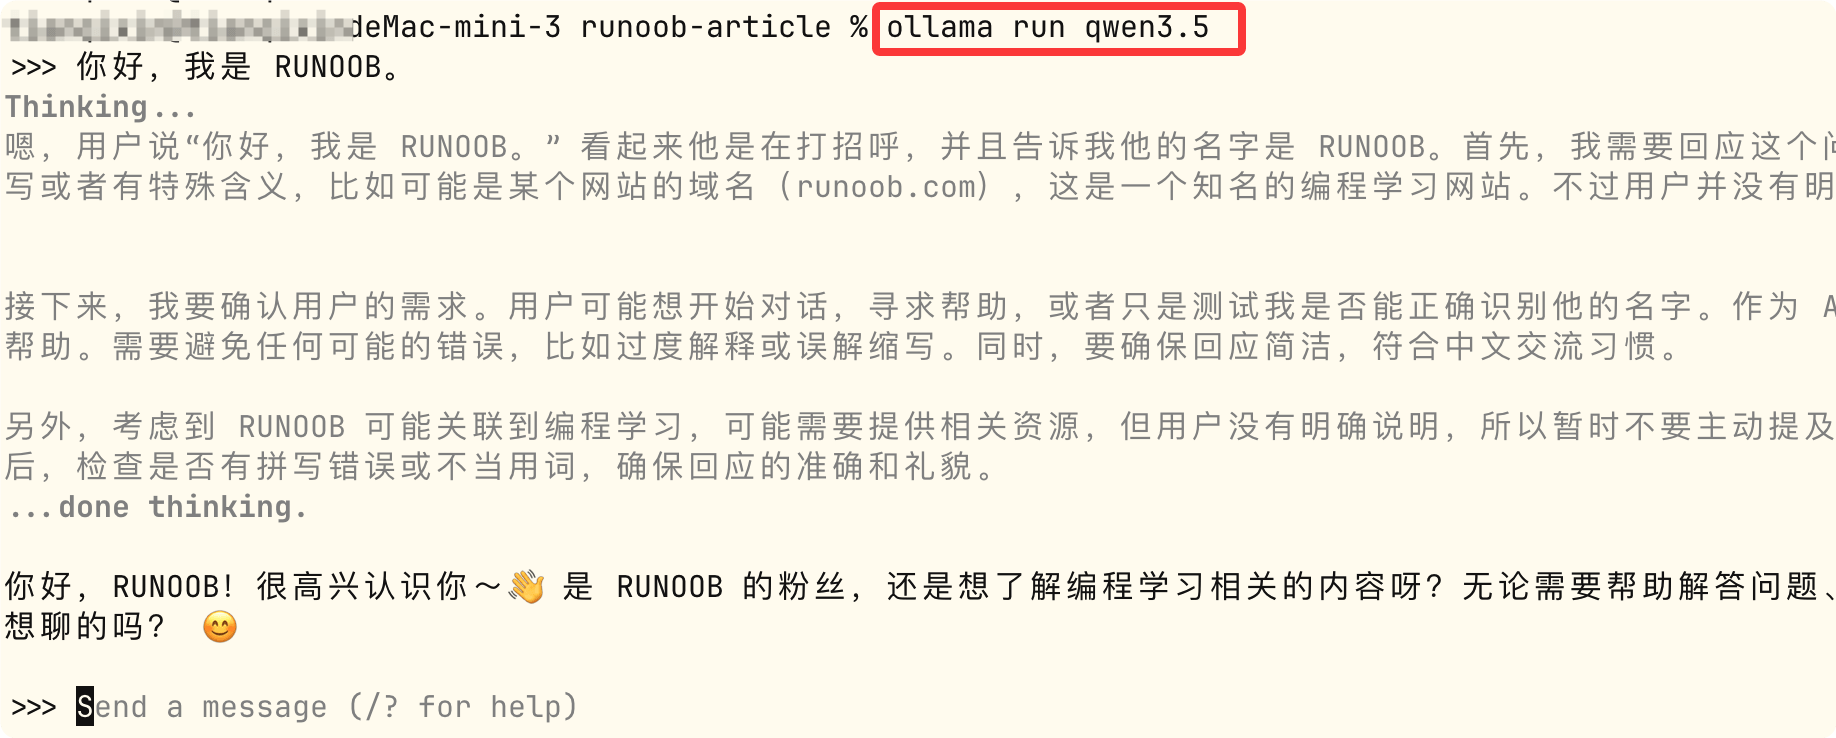
Start it with a single command, and chat directly once the model is running:
ollama run qwen3.5
This command will start the Qwen3.5 model locally and enter an interactive chat terminal. If the model is not available locally, it will automatically download it first, then start.
Related Links
Ollama official website:https://ollama.com/
-
GitHub open-source repository:https://github.com/ollama/ollama
Model library:https://ollama.com/search
-
Ollama official documentation:https://github.com/ollama/ollama/tree/main/docs