Multimodal Pre-trained Models
Multimodal Pre-trained Models refer to deep learning models that can simultaneously process and understandmultiple data modalities(such as text, images, audio, etc.). Unlike traditional unimodal models, these models learn the associations and correspondences between different modalities through large-scale pre-training.
Core Advantages of Multimodal Learning
- Complementary information: Different modalities can provide complementary information (e.g., images provide visual information, text provides semantic information)
- Enhanced robustness: When data from one modality is missing or of poor quality, other modalities can provide support
- Expanded application scenarios: Supports richer cross-modal tasks (such as image-text retrieval, image captioning, etc.)
CLIP: A Milestone in Image-Text Contrastive Learning
Basic Concepts
CLIP (Contrastive Language-Image Pre-training) is a multimodal model proposed by OpenAI in 2021 that establishes associations between images and text through contrastive learning.
CLIP consists of two core components:
- Image Encoder: Converts images into feature vectors (e.g., using Vision Transformer or ResNet).
- Text Encoder: Converts text descriptions into feature vectors (e.g., using Transformer).
Workflow:
- Input:
- Image-text pairs (e.g., a photo of a dog + the description "a photo of a dog").
- Encoding:
- The image encoder extracts image features, and the text encoder extracts text features.
- Contrastive learning:
- Compute a similarity matrix for all image-text pairs and optimize the model using a loss function (such as InfoNCE), so that features of matched pairs are pulled together and unmatched pairs are pushed apart.
The feature vectors output by both encoders are mapped into the same semantic space, aligning image and text representations through contrastive learning.
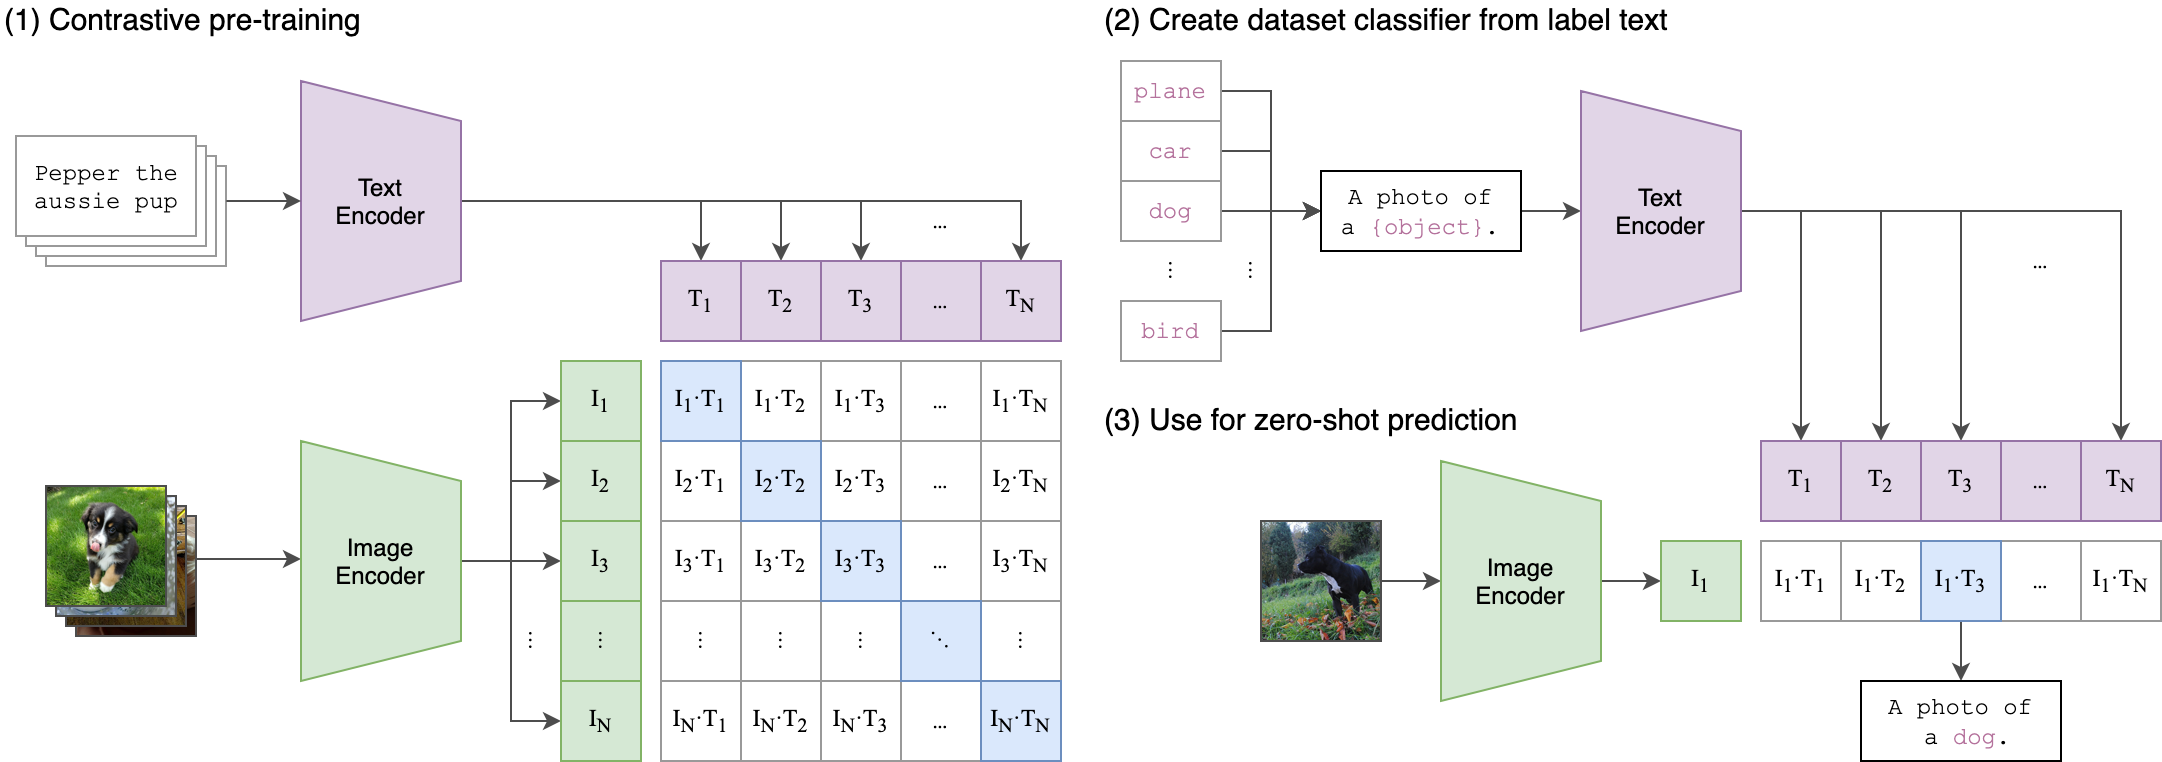
Explanation of Key Parts in the Figure
Table section: Contrastive learning matrix
The table shows the similarity computation for image-text pairs (assuming there areNtexts and4images):
- Rows (images):
I1, I2, I3, I4Represent different image features. - Columns (texts):
T1, T2, ..., TNRepresent different text features. - Cell values(e.g.,
I1-T1): The cosine similarity between the feature vectors of imageI1and textT1.
Objective:
Maximize the similarity on the diagonal (correct pairs, e.g.,I1-T1), and minimize off-diagonal similarity (incorrect pairs, e.g.,I1-T2). This is the core idea of contrastive learning.
Example section
- Image examples:
- "Pepper the aussie pup" (a photo of an Australian Shepherd puppy).
- "Planer car dog" (possibly noise or incorrect annotation; it should actually be template text of "A photo of a (object)").
- Text template:
- "A photo of a (object)" is a commonly used text prompt template during CLIP pre-training, used to generalize across different categories (e.g., "a photo of a dog").
Model Architecture
- Dual-encoder architecture:
- Image encoder: Typically Vision Transformer (ViT) or ResNet
- Text encoder: Based on the Transformer architecture
- Contrastive learning objective:
- Positive pairs (matched image-text pairs) are close in the feature space
- Negative pairs (mismatched image-text pairs) are far apart in the feature space
Training Process
Example
image_features = image_encoder(image_batch) # Image feature extraction
text_features = text_encoder(text_batch) # Text feature extraction
# Compute similarity matrix
logits = torch.matmul(image_features, text_features.T) * temperature
labels = torch.arange(batch_size) # Diagonal is positive samples
# Symmetric contrastive loss
loss_img = cross_entropy(logits, labels)
loss_txt = cross_entropy(logits.T, labels)
total_loss = (loss_img + loss_txt)/2
Application Scenarios
- Zero-shot image classification: Classify new categories without fine-tuning
- Image-text retrieval: Enable efficient text-to-image or image-to-text search
- Content moderation: Identify image content that does not match text descriptions
DALL-E: The Magic of Text-to-Image Generation
Basic Concepts
DALL-E is a text-to-image generation model developed by OpenAI that can generate high-quality images from natural language descriptions.
Technical Features
Two-stage training:
- Stage 1: A discrete variational autoencoder (dVAE) compresses images into visual tokens
- Stage 2: An autoregressive Transformer learns the mapping from text to visual tokens
Key innovations:
- Treat image generation as a sequence prediction problem
- Uses a 12-billion parameter Transformer model
Example Generation Process
Example
text = "A Shiba Inu wearing a spacesuit playing a video game on a space station"
text_tokens = tokenizer(text) # Text encoding
image_tokens = transformer.generate(text_tokens) # Generate visual tokens
image = dvae.decode(image_tokens) # Decode into an image
Model Evolution
| Version | Major improvements | Generation capability |
|---|---|---|
| DALL-E 1 | Base architecture | 256x256 resolution |
| DALL-E 2 | Diffusion model | 1024x1024 resolution, more precise |
| DALL-E 3 | Integrated with ChatGPT | More complex prompt understanding |
Other Important Multimodal Models
ALIGN(Google)
- Trained on noisy web-scale data
- Demonstrated the effectiveness of large-scale weakly supervised data
Flamingo(DeepMind)
- Processes interleaved multimodal sequences (e.g., alternating text and images)
- Supports few-shot learning
BEiT-3(Microsoft)
- Unified multimodal pre-training framework
- Performs excellently on image, text, and vision-language tasks
Application Challenges of Multimodal Models
- Data requirements: Requires massive amounts of high-quality multimodal aligned data
- Computational cost: Training these models requires enormous computational resources
- Evaluation difficulties: Lack of unified evaluation standards for multimodal tasks
- Bias issues: May amplify social biases present in training data
Hands-on Practice: Zero-shot Classification with CLIP
Example
import torch
from PIL import Image
# Load model and preprocessing
device = "cuda" if torch.cuda.is_available() else "cpu"
model, preprocess = clip.load("ViT-B/32", device=device)
# Prepare inputs
image = preprocess(Image.open("dog.jpg")).unsqueeze(0).to(device)
text_inputs = clip.tokenize(["a dog", "a cat", "a bird"]).to(device)
# Compute features
with torch.no_grad():
image_features = model.encode_image(image)
text_features = model.encode_text(text_inputs)
# Compute similarity
logits = (image_features @ text_features.T).softmax(dim=-1)
print("Predicted probabilities:", logits.cpu().numpy())
Future Development Directions
- More efficient architectures: Reduce computational cost and improve inference speed
- More modality fusion: Incorporate more modalities such as audio and video
- Causal understanding capability: Enhance the model's deep understanding of multimodal content
- Controllable generation: Improve precise control and editability of generated content
Multimodal pre-trained models are reshaping the way humans interact with machines. From CLIP's cross-modal understanding to DALL-E's creative generation, these technologies are opening up entirely new possibilities for AI applications.
Other Extensions