Codex Model Selection
Codex supports multiple models. Understanding the characteristics of each model helps you choose the right one for your scenario.
Desktop version can switch at the bottom right corner of the input box

Codex CLI can be used/modelCommand Switching:
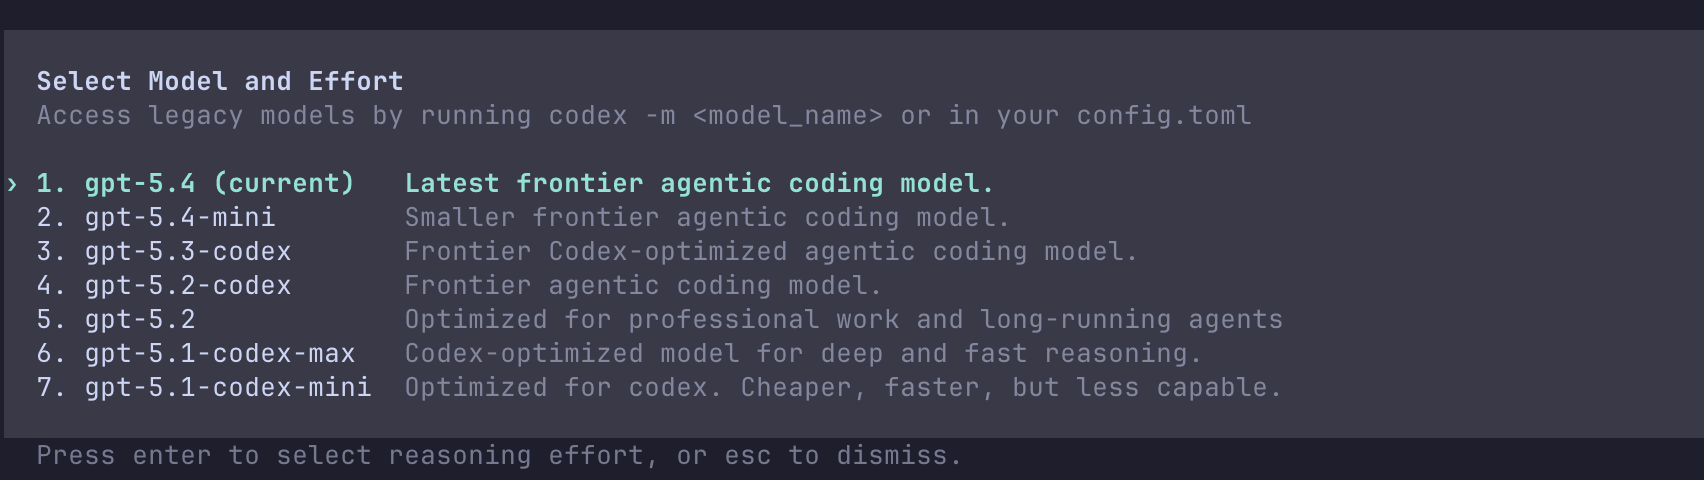
Available Models
Codex currently supports the following models:
| Model | Type | Features | Applicable scenarios |
|---|---|---|---|
| gpt-5.4 | Flagship | Strongest capability, deep reasoning | Complex tasks, architecture design |
| gpt-5.4-mini | Lightweight | Fast response, lower cost | Simple tasks, rapid iteration |
| gpt-5.3-codex | Pro | Programming optimization, code specialization | Code writing, bug fixing |
| gpt-5.3-codex-spark | Fast | Ultra-fast response, high-frequency interaction | Real-time collaboration, quick Q&A |
Detailed explanation of model features
GPT-5.4
Flagship model, offering the strongest reasoning and creative capabilities.
| Features | Description |
|---|---|
| Reasoning Depth | Deep analysis of complex problems |
| Context Understanding | Understanding large codebase structure |
| Multi-step Tasks | Handling complex workflows |
| Accuracy | High accuracy, reduced rework |
Applicable scenarios
- Architecture design and refactoring
- Complex bug analysis and fixing
- Multi-module coordinated development
- Code review and quality analysis
GPT-5.4-mini
Lightweight model, fast response, suitable for daily development.
| Features | Description |
|---|---|
| Response Speed | Faster than flagship models |
| Cost Efficiency | Lower token consumption |
| Daily Tasks | Suitable for routine development operations |
Applicable scenarios
- Simple feature implementation
- Code formatting and refactoring
- Documentation Writing
- Quick Q&A
GPT-5.3-Codex
A model specifically optimized for programming tasks.
| Features | Description |
|---|---|
| Code Expertise | Trained specifically for programming tasks |
| Language Coverage | Supports multiple programming languages |
| Code Quality | High-quality generated code |
Applicable scenarios
- Code writing and generation
- Bug fixing and debugging
- Code Refactoring
- Test Writing
GPT-5.3-Codex-Spark
Ultra-fast response model, suitable for high-frequency interaction scenarios.
| Features | Description |
|---|---|
| Ultra-fast Response | Fastest response speed |
| Real-time Collaboration | Suitable for interactive development |
| Pro Exclusive | Available only in the Pro plan |
Applicable scenarios
- Real-time code Q&A
- Rapid prototype validation
- High-frequency iterative development
Reasoning intensity configuration
You can adjust the model's reasoning effort to balance speed and depth.
Reasoning intensity levels
| Level | Description | Features |
|---|---|---|
minimal | Minimal Reasoning | Fastest response, suitable for simple tasks |
low | Low Reasoning Intensity | Fast but with some analysis |
medium | Medium Reasoning | Balanced speed and depth (default) |
high | High Reasoning Intensity | Deep analysis, suitable for complex tasks |
xhigh | Ultra-high Reasoning | Strongest reasoning, slowest response |
Configure reasoning intensity
Reasoning intensity settings
codex --reasoning-effort high
# Configuration File
[mycode4 type="toml"]
model_reasoning_effort = "high"
# Switch in Session /model gpt-5.4 --reasoning-effort xhigh [/mycode4]
Reasoning Summary
Control how much detail Codex displays in its reasoning process.
Summary Mode
| Mode | Description |
|---|---|
auto | Automatically determines level of detail (default) |
concise | Brief Summary |
detailed | Detailed reasoning process |
none | Do not show reasoning summary |
Reasoning summary settings
model_reasoning_summary = "detailed"
Model Switching
Switch between different models for different scenarios.
Switching Method
Switch model
/model gpt-5.4
/model gpt-5.4-mini
/model gpt-5.3-codex
# With Reasoning Strength
/model gpt-5.4 --reasoning-effort high
# In-App Switching
Click the model selector to select the target model
Scenario switching suggestions
| Scenarios | Recommended Model | Reasoning Strength |
|---|---|---|
| Architecture Design | gpt-5.4 | high/xhigh |
| Complex Refactoring | gpt-5.4 | high |
| Bug Fix | gpt-5.3-codex | medium |
| Daily Coding | gpt-5.4-mini | low/medium |
| Quick Q&A | gpt-5.4-mini | minimal |
| Real-time Collaboration | gpt-5.3-codex-spark | minimal |
Service Tier
Choosing different service tiers affects response priority.
Service tier options
| Tier | Description |
|---|---|
flex | Elastic service, responses may be slightly slower (default). |
fast | Priority service, faster response |
Service tier settings
service_tier = "fast"
Models & Plans
Model support varies by plan:
| Plan | Available Models |
|---|---|
| Free | Base Model |
| Plus | gpt-5.4, gpt-5.4-mini, gpt-5.3-codex |
| Pro | All models + Spark + higher limits. |
| API Key | Billed per token, supports mainstream models. |
Cost Considerations
Token consumption comparison
| Model | Relative Cost |
|---|---|
| gpt-5.4 | Highest |
| gpt-5.3-codex | Medium-High |
| gpt-5.4-mini | Relatively Low |
| gpt-5.3-codex-spark | Low |
Cost optimization suggestions
- Use mini or Spark models for simple tasks.
- Use medium reasoning effort for daily development.
- Use the flagship model and high reasoning effort only for complex tasks.
- Use /compact to compress context and reduce token consumption.
Best Practices
Model selection principles
- Choose a model based on task complexity
- Balance response speed and reasoning depth
- Prioritize accuracy for complex tasks
- Prioritize response speed for high-frequency interactions
Configuration Suggestions
Recommended Configuration
model = "gpt-5.4-mini"
model_reasoning_effort = "medium"
model_reasoning_summary = "auto"
# Temporary Switch for Complex Tasks
# /model gpt-5.4 --reasoning-effort high
FAQ
Q: Which model is best for code writing?
gpt-5.3-codex is optimized for programming tasks and is suitable for most code-writing scenarios.
Q: How to balance speed and quality?
For daily tasks, use gpt-5.4-mini with medium reasoning intensity; switch to gpt-5.4 with high reasoning intensity for complex tasks.
Q: What are the advantages of the Spark model?
The Spark model responds the fastest, suitable for high-frequency interaction and real-time collaboration, and is only available in the Pro plan.
Q: How does reasoning intensity affect results?
Higher reasoning effort means Codex will perform deeper analysis, but response time will be longer.
other extensions