In Zookeeper, the ZAB protocol is mainly relied upon to achieve distributed data consistency.
The ZAB protocol is divided into two parts:
- Message Broadcast
- Crash Recovery
Message Broadcast
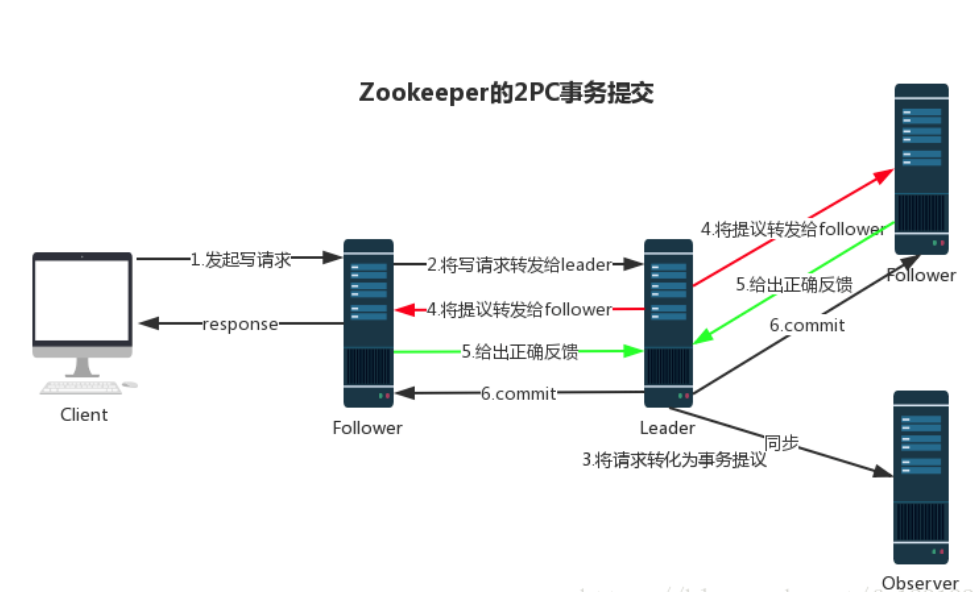
Zookeeper uses a single main process, the Leader, to receive and process all transaction requests from clients, and uses the atomic broadcast protocol of the ZAB protocol to broadcast transaction requests as Proposal proposals to all Follower nodes. When more than half of the Follower servers in the cluster provide correct ACK feedback, the Leader will send a commit message to all Follower servers again to commit this proposal. This process can be abbreviated as 2PC transaction commit. Refer to the figure below for the entire process. Note that Observer nodes are only responsible for synchronizing Leader data and do not participate in the 2PC data synchronization process.
Crash Recovery
Under normal circumstances, the message broadcast mode works well. However, once the Leader server crashes, or due to network issues the Leader server loses communication with more than half of the Followers, it enters crash recovery mode, and a new Leader server needs to be elected. During this process, two potential data inconsistency hazards may arise, which need to be avoided through the features of the ZAB protocol.
- 1. The Leader server crashes immediately after sending the commit message
- 2. The Leader server crashes immediately after just proposing a proposal
The recovery mode of the ZAB protocol uses the following strategies:
- 1. Elect the node with the largest zxid as the new leader
- 2. The new leader processes the uncommitted messages in the transaction log
The next chapter explains the leader election process in detail.